Introduction
Comparing Multiple Groups compared means and distributions across several groups with ANOVA and Kruskal-Wallis.
This chapter asks three questions.
- How do we compare groups with a regression?
- Treatment coding and effect coding: these rewrite the ANOVA comparison as a regression. Treatment coding compares each group with a reference group, and effect coding compares it with the mean across group means.
- What does a continuous predictor add to a group comparison?
- Regression with factors and fixed effects: these put a factor and a continuous predictor in one model, where each group gets its own intercept.
- Nested-model \(F\)-tests: these reuse the \(F\)-statistic to ask whether each added layer of a model adds information.
- How sure are we?
- Permutation test: this imposes a null relationship by shuffling a factor variable, the same recipe as for ANOVA.
- Random subsampling: this keeps each observation intact and checks how estimates vary when some observations are omitted. It extends the jackknife by deleting several observations at a time.
None of these methods turns an observational relationship into a causal effect. The word effect in effect coding names a parameterization, not a causal claim.
We continue with the group comparison from Comparing Multiple Groups.
Code
## MAIN EXAMPLE
# 3294 US workers, one row per worker.
# wage is the hourly wage in 1980 dollars.
# school and exper are years of schooling and experience.
data(Wages1, package='Ecdat')
xy_hat <- Wages1
# Three-level schooling factor, as in Comparing Multiple Groups
xy_hat$school_g <- cut(xy_hat$school, breaks=c(0, 11, 12, 16), labels=c('<12', '12', '>12'))
table(xy_hat$school_g)
##
##  <12   12  >12
## 1353 1188  753
# The groups differ in size, which matters for effect coding below.
Regression
ANOVA is a special case of linear regression where the only explanatory variables are group indicators.
ANOVA
The model \(\hat{y}_{ig} = b_{0} + \sum_{g=2}^{G} b_{g} \hat{d}_{ig} + \hat{e}_{ig}\) produces the same \(F\)-statistic as the ANOVA model. After fitting, \(\hat{b}_{0}\) estimates the mean of the reference group and each \(\hat{b}_{g}\) estimates the difference between group \(g\) and the reference. This default representation is called treatment coding.
Code
## MAIN EXAMPLE
# Compare the group means to treatment-coded coefficients.
m_g_hat <- aggregate(wage ~ school_g, data=xy_hat, FUN=mean)[,'wage']
m_g_hat
## [1] 4.990937 5.668354 7.275887
# Mean wages rise with schooling, from about 4.99 to 7.28 dollars.

# The intercept is the reference mean.
m_g_hat - m_g_hat[1]
## [1] 0.0000000 0.6774177 2.2849502

# Each remaining coefficient is a difference from the reference.
reg_lm <- lm(wage ~ school_g, data=xy_hat)
coef(reg_lm)
## (Intercept)  school_g12 school_g>12
##   4.9909367   0.6774177   2.2849502
# The reference is the first level, fewer than 12 years of schooling.
# The >12 group earns about 2.28 dollars more per hour than the reference.
The ANOVA table for a regression with a single factor is therefore the same as the table from aov().
Code
reg_aov <- aov(wage ~ school_g, data=xy_hat)
anova(reg_aov)
## Analysis of Variance Table
##
## Response: wage
##             Df Sum Sq Mean Sq F value    Pr(>F)
## school_g     2   2541 1270.27  128.02 < 2.2e-16 ***
## Residuals 3291  32654    9.92
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
anova(reg_lm)
## Analysis of Variance Table
##
## Response: wage
##             Df Sum Sq Mean Sq F value    Pr(>F)
## school_g     2   2541 1270.27  128.02 < 2.2e-16 ***
## Residuals 3291  32654    9.92
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# Both tables report the same F-statistic, about 128.
Repeat the comparison with murder arrest rates across the four census regions.
Code
# All 50 US states, with murder arrests per 100,000 in the column Murder.
xy2_hat <- USArrests
# The built-in state.region lists regions in the same state order as USArrests.
xy2_hat$Region <- state.region
table(xy2_hat$Region)
##
##     Northeast         South North Central          West
##             9            16            12            13

# Compare the regional means to treatment-coded coefficients.
m2_g_hat <- aggregate(Murder ~ Region, data=xy2_hat, FUN=mean)[,'Murder']
m2_g_hat
## [1]  4.700000 11.706250  5.700000  7.030769

# The intercept is the reference mean.
m2_g_hat - m2_g_hat[1]
## [1] 0.000000 7.006250 1.000000 2.330769

# Each remaining coefficient is a difference from the reference.
reg2_lm <- lm(Murder ~ Region, data=xy2_hat)
coef(reg2_lm)
##         (Intercept)         RegionSouth RegionNorth Central          RegionWest
##            4.700000            7.006250            1.000000            2.330769
# The reference is the Northeast.
# The South's mean is about 7 arrests per 100,000 higher.

reg2_aov <- aov(Murder ~ Region, data=xy2_hat)
anova(reg2_aov)
## Analysis of Variance Table
##
## Response: Murder
##           Df Sum Sq Mean Sq F value    Pr(>F)
## Region     3 391.24 130.412  11.144 1.282e-05 ***
## Residuals 46 538.32  11.703
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
anova(reg2_lm)
## Analysis of Variance Table
##
## Response: Murder
##           Df Sum Sq Mean Sq F value    Pr(>F)
## Region     3 391.24 130.412  11.144 1.282e-05 ***
## Residuals 46 538.32  11.703
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# Both tables report the same F-statistic, about 11.1.
Suppose there are \(G=3\) groups with means \(\hat{m}_{1}=4\), \(\hat{m}_{2}=7\), and \(\hat{m}_{3}=5\). Using group 1 as the reference, the regression coefficients are \(\hat{b}_{0}=4\), \(\hat{b}_{2}=7-4=3\), and \(\hat{b}_{3}=5-4=1\). The intercept equals the reference-group mean, and each slope equals a difference from that reference.
Code
# Verify the treatment-coded coefficients.
y0_hat <- c(3, 4, 5, 6, 7, 8, 4, 5, 6)
g <- factor(c(1, 1, 1, 2, 2, 2, 3, 3, 3))
coef(lm(y0_hat ~ g))
## (Intercept)          g2          g3
##           4           3           1
Effect Coding
Treatment coding makes every coefficient depend on which group R selects as the reference. Effect coding instead compares each displayed group with the mean across all group means.
With \(G\) factor levels, effect coding creates \(G-1\) columns. For column \(g\), observations in level \(g\) receive \(1\), observations in the omitted level receive \(-1\), and observations in the other levels receive \(0\). In a factor-only regression, \(\hat{b}_{0}\) is the unweighted mean of the \(G\) group means, each displayed \(\hat{b}_{g}\) is that group’s deviation from the unweighted mean, and the omitted group’s effect is \(-\sum_{g=1}^{G-1}\hat{b}_{g}\).
Effect coding is useful when no group is a natural reference and the deviations from a common center are easier to discuss than several pairwise differences. When the groups contain different numbers of observations, the unweighted mean of the group means generally differs from the observation-weighted mean across all observations.
Code
## MAIN EXAMPLE
# Display the sum-to-zero contrast matrix used for effect coding.
effect_matrix <- contr.sum(nlevels(xy_hat$school_g))
rownames(effect_matrix) <- levels(xy_hat$school_g)
effect_matrix
##     [,1] [,2]
## <12    1    0
## 12     0    1
## >12   -1   -1

# Apply contrasts to this model only, without changing global options.
reg_effect <- lm(
    wage ~ school_g,
    data=xy_hat,
    contrasts=list(school_g='contr.sum')
)
coef(reg_effect)
## (Intercept)   school_g1   school_g2
##   5.9783926  -0.9874560  -0.3100382

# Compare each group mean with the unweighted mean of group means.
group_means <- aggregate(wage ~ school_g, data=xy_hat, FUN=mean)
effect_mean <- mean(group_means[,'wage'])
group_effects <- group_means[,'wage'] - effect_mean
data.frame(
    school_g=group_means[,'school_g'],
    group_mean=group_means[,'wage'],
    coded_effect=group_effects
)
##   school_g group_mean coded_effect
## 1      <12   4.990937   -0.9874560
## 2       12   5.668354   -0.3100382
## 3      >12   7.275887    1.2974942
# The center is about 5.98 dollars.
# Only workers with more than 12 years of schooling are above it.

# Recover the omitted effect, for more than 12 years of schooling.
# It follows from the sum-to-zero restriction.
-sum(coef(reg_effect)[-1])
## [1] 1.297494
Changing the contrasts changes the meanings of the coefficients, but not the fitted values, residuals, \(\hat{R}^2\), or global \(F\)-statistic.
Code
treatment_F <- anova(reg_lm)[['F value']][1]
effect_F <- anova(reg_effect)[['F value']][1]

c(
    maximum_fitted_difference=max(abs(fitted(reg_lm) - fitted(reg_effect))),
    maximum_residual_difference=max(abs(resid(reg_lm) - resid(reg_effect))),
    treatment_F=treatment_F,
    effect_F=effect_F
)
##   maximum_fitted_difference maximum_residual_difference
##                5.151435e-14                5.134781e-14
##                 treatment_F                    effect_F
##                1.280237e+02                1.280237e+02
# The fitted values and residuals differ only by rounding error.
# Both codings give the same F-statistic, about 128.
Compare the effect-coded intercept with the overall mean of wage across all workers. Use table(xy_hat$school_g) and the group means to explain why these numbers differ. Then change the order of the factor levels and verify that the fitted values remain unchanged.
Code
coef(reg_effect)['(Intercept)']
## (Intercept)
##    5.978393
# The effect-coded intercept is about 5.98 dollars.

mean(xy_hat[, 'wage'])
## [1] 5.757585
# The overall mean is about 5.76 dollars.
Repeat effect coding with murder arrest rates across the census regions. Is the effect-coded intercept above or below the overall mean, and why?
Code
# All 50 US states, with the four census regions as a factor.
xy2_hat <- USArrests
xy2_hat$Region <- state.region

# Display the sum-to-zero contrast matrix used for effect coding.
effect2_matrix <- contr.sum(nlevels(xy2_hat$Region))
rownames(effect2_matrix) <- levels(xy2_hat$Region)
effect2_matrix
##               [,1] [,2] [,3]
## Northeast        1    0    0
## South            0    1    0
## North Central    0    0    1
## West            -1   -1   -1

# Apply contrasts to this model only, without changing global options.
reg2_effect <- lm(
    Murder ~ Region,
    data=xy2_hat,
    contrasts=list(Region='contr.sum')
)
coef(reg2_effect)
## (Intercept)     Region1     Region2     Region3
##    7.284255   -2.584255    4.421995   -1.584255
# The effect-coded intercept is about 7.28.

# Compare each regional mean with the unweighted mean of group means.
region_means <- aggregate(Murder ~ Region, data=xy2_hat, FUN=mean)
effect2_mean <- mean(region_means[,'Murder'])
region_effects <- region_means[,'Murder'] - effect2_mean
data.frame(
    region=region_means[,'Region'],
    group_mean=region_means[,'Murder'],
    coded_effect=region_effects
)
##          region group_mean coded_effect
## 1     Northeast   4.700000   -2.5842548
## 2         South  11.706250    4.4219952
## 3 North Central   5.700000   -1.5842548
## 4          West   7.030769   -0.2534856

# Recover the omitted West effect from the sum-to-zero restriction.
-sum(coef(reg2_effect)[-1])
## [1] -0.2534856

mean(xy2_hat[, 'Murder'])
## [1] 7.788
# The overall mean across all states is about 7.79.
Regression with Factors
We can extend the group-comparison model by adding continuous predictors alongside the factor. For example, we might ask whether group differences persist after holding a continuous predictor fixed.
Code
## MAIN EXAMPLE
# Add a continuous predictor to the schooling model.
reg_combined <- lm(wage ~ school_g + exper, data=xy_hat)
summary(reg_combined)
##
## Call:
## lm(formula = wage ~ school_g + exper, data = xy_hat)
##
## Residuals:
##    Min     1Q Median     3Q    Max
## -6.754 -2.027 -0.497  1.441 35.133
##
## Coefficients:
##             Estimate Std. Error t value Pr(>|t|)
## (Intercept)  4.15373    0.21102  19.684  < 2e-16 ***
## school_g12   0.64024    0.12520   5.114 3.34e-07 ***
## school_g>12  2.32815    0.14317  16.261  < 2e-16 ***
## exper        0.10452    0.02409   4.339 1.48e-05 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
##
## Residual standard error: 3.141 on 3290 degrees of freedom
## Multiple R-squared:  0.07746,    Adjusted R-squared:  0.07662
## F-statistic: 92.09 on 3 and 3290 DF,  p-value: < 2.2e-16
# Holding experience fixed, the gaps from the <12 group are about 0.64 and 2.33.
# Those are close to the raw gaps of about 0.68 and 2.28.
# Each year of experience goes with about 0.10 dollars more per hour.
Holding a predictor fixed changes the conditional association being summarized. It does not by itself remove confounding, reverse causation, measurement error, or other reasons that a regression coefficient may not be causal.
Repeat the regression with murder arrest rates, and ask whether regional differences persist after holding assault arrest rates fixed.
Code
# All 50 US states, with assault arrests per 100,000 in the column Assault.
xy2_hat <- USArrests
xy2_hat$Region <- state.region

# Add a continuous predictor to the regional model.
reg2_combined <- lm(Murder ~ Region + Assault, data=xy2_hat)
summary(reg2_combined)
##
## Call:
## lm(formula = Murder ~ Region + Assault, data = xy2_hat)
##
## Residuals:
##     Min      1Q  Median      3Q     Max
## -6.4434 -1.2104  0.0058  1.6280  6.0123
##
## Coefficients:
##                     Estimate Std. Error t value Pr(>|t|)
## (Intercept)         0.216516   0.936455   0.231 0.818201
## RegionSouth         3.702630   1.021206   3.626 0.000731 ***
## RegionNorth Central 1.224174   0.986690   1.241 0.221151
## RegionWest          0.187047   1.007021   0.186 0.853481
## Assault             0.035396   0.004474   7.912 4.63e-10 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
##
## Residual standard error: 2.237 on 45 degrees of freedom
## Multiple R-squared:  0.7578, Adjusted R-squared:  0.7363
## F-statistic:  35.2 on 4 and 45 DF,  p-value: 2.511e-13
# Holding Assault fixed, the South's gap from the Northeast is about 3.7.
# That is about half of its raw gap of about 7.
Fixed Effects
The dummy-variable model treats each group as having its own intercept. This framing is useful when group identity captures features we cannot otherwise measure.
One common case is observations of individuals over several time periods. Then you may have two factor variables. An unordered factor indicates who an individual is, and an ordered factor indicates the time period (Mundlak 1978; Wooldridge 2010). There are many other cases you see factor variables, including spatial ID’s in purely cross sectional data.
Be careful not to handle categorical data as if they were cardinal. E.g., generate city data with Leipzig=1, Lausanne=2, LosAngeles=3, … and then include city as if it were a cardinal number (that’s a big no-no). The same applies to ordinal data; PopulationLeipzig=2, PopulationLausanne=3, PopulationLosAngeles=1. Instead, give each city its own dummy variable, or equivalently its own fixed effect.
Fixed effects are group-specific intercepts that absorb every time-invariant feature of the group, entering the regression as \[
\hat{y}_{i} = \sum_{k=1}^{K} b_{k} \hat{x}_{ik} + \sum_{g}\hat{d}_{ig}b_{g} + \hat{e}_{i}.
\] Including the dummy variables directly in OLS or using a dedicated routine such as fixest::feols() gives the same coefficients on the remaining regressors and the same residuals.
Fixed effects are useful when a factor predicts the outcome but the coefficients on its individual levels are not the main object of interest. The coefficient on another predictor then describes its partial relationship with the outcome after removing level differences across the factor.
Code
## MAIN EXAMPLE
# Estimate the experience coefficient with explicit schooling indicators.
reg_dv <- lm(wage ~ -1 + exper + school_g, data=xy_hat)
coef(reg_dv)['exper']
##     exper
## 0.1045248

# Estimate the same coefficient by absorbing the schooling group effects.
reg_fe <- fixest::feols(wage ~ exper | school_g, data=xy_hat)
coef(reg_fe)
##     exper
## 0.1045248
# Both give about 0.105 dollars per hour for each year of experience.
Repeat the comparison with murder arrest rates, using assault arrest rates as the other predictor and census regions as the fixed effects.
Code
# All 50 US states, with the four census regions as a factor.
xy2_hat <- USArrests
xy2_hat$Region <- state.region

# Estimate the Assault coefficient with explicit region indicators.
reg2_dv <- lm(Murder ~ -1 + Assault + Region, data=xy2_hat)
coef(reg2_dv)['Assault']
##    Assault
## 0.03539592

# Estimate the same coefficient by absorbing the region effects.
reg2_fe <- fixest::feols(Murder ~ Assault | Region, data=xy2_hat)
coef(reg2_fe)
##    Assault
## 0.03539592
# Both give about 0.035 murder arrests per assault arrest.
With fixed effects, we can also compute averages for each group: \(\hat{m}_{Yg}=\sum_{i}^{n_{g}}\hat{y}_{ig}/n_{g}\), where group \(g\) has \(n_{g}\) observations denoted \(\hat{y}_{ig}\). We can construct a between estimator from \(\hat{m}_{Yg}=b_{0}+\hat{m}_{Xg}b_{1}\). Alternatively, we can subtract each group average to construct a within estimator: \((\hat{y}_{ig}-\hat{m}_{Yg})=(\hat{x}_{ig}-\hat{m}_{Xg})b_{1}\). Absorbing fixed group differences does not remove confounders that vary within a group.
Comparing Models
The ANOVA \(F\)-statistic also compares nested regression models. Under additional parametric assumptions, the statistic follows an \(F\) distribution under the null. We can build a sequence of nested models, each adding one layer of complexity, to see which predictors contribute. The first asks whether group means differ, the second whether a continuous predictor adds explanatory power, and the third whether that predictor’s slope varies across groups (Brambor et al. 2006; Balli and Sørensen 2013).
Code
## MAIN EXAMPLE
# Order the nested models from simplest to most complex.
reg0 <- lm(wage ~ 1, data=xy_hat)
reg1 <- lm(wage ~ school_g, data=xy_hat)
reg2 <- lm(wage ~ school_g + exper, data=xy_hat)
reg3 <- lm(wage ~ school_g * exper, data=xy_hat)

# Test whether the schooling groups add information.
anova(reg0, reg1)
## Analysis of Variance Table
##
## Model 1: wage ~ 1
## Model 2: wage ~ school_g
##   Res.Df   RSS Df Sum of Sq      F    Pr(>F)
## 1   3293 35194
## 2   3291 32654  2    2540.5 128.02 < 2.2e-16 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# F is about 128, and the p-value is essentially zero.

# Test whether experience adds information beyond the schooling groups.
anova(reg1, reg2)
## Analysis of Variance Table
##
## Model 1: wage ~ school_g
## Model 2: wage ~ school_g + exper
##   Res.Df   RSS Df Sum of Sq      F    Pr(>F)
## 1   3291 32654
## 2   3290 32468  1    185.77 18.824 1.476e-05 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# F is about 19, and the p-value is about 0.000015.

# Test whether the experience slope differs by schooling group.
anova(reg2, reg3)
## Analysis of Variance Table
##
## Model 1: wage ~ school_g + exper
## Model 2: wage ~ school_g * exper
##   Res.Df   RSS Df Sum of Sq      F   Pr(>F)
## 1   3290 32468
## 2   3288 32331  2    136.84 6.9581 0.000965 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# F is about 7, and the p-value is about 0.001.
# All three tests reject, although RSS falls by only about 8% in total.
Code
# Reproduce the first nested-model F-test by hand.
rss0 <- sum(resid(reg0)^2)
rss1 <- sum(resid(reg1)^2)
df0 <- df.residual(reg0)
df1 <- df.residual(reg1)
F <- ((rss0 - rss1)/(df0 - df1))/(rss1/df1)
# Ask for the upper tail directly, since 1 - pf() would round this p to 0.
p <- pf(F, df0 - df1, df1, lower.tail=FALSE)
cbind(F, p)
##             F            p
## [1,] 128.0237 2.863426e-54
# F matches the first table above, about 128.
# The p-value, about 3e-54, is below the 2.2e-16 limit that table prints.
The sequence of \(F\)-tests builds from simple to complex. The first test asks whether the factor adds information at all. The second asks whether a continuous predictor adds information beyond the factor. The third asks whether that predictor’s relationship with the outcome varies across groups. A small \(p\)-value rejects the simpler model, but it does not explain why the relationship exists.
Build the same sequence of nested models for murder arrest rates, with census regions as the factor and assault arrest rates as the continuous predictor. Does the slope vary across regions?
Code
# All 50 US states, with the four census regions as a factor.
xy2_hat <- USArrests
xy2_hat$Region <- state.region

# Order the nested models from simplest to most complex.
reg2_0 <- lm(Murder ~ 1, data=xy2_hat)
reg2_1 <- lm(Murder ~ Region, data=xy2_hat)
reg2_2 <- lm(Murder ~ Region + Assault, data=xy2_hat)
reg2_3 <- lm(Murder ~ Region * Assault, data=xy2_hat)

# Test whether Region adds information.
anova(reg2_0, reg2_1)
## Analysis of Variance Table
##
## Model 1: Murder ~ 1
## Model 2: Murder ~ Region
##   Res.Df    RSS Df Sum of Sq      F    Pr(>F)
## 1     49 929.55
## 2     46 538.32  3    391.24 11.144 1.282e-05 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# F is about 11, and the p-value is about 0.000013.

# Test whether Assault adds information beyond Region.
anova(reg2_1, reg2_2)
## Analysis of Variance Table
##
## Model 1: Murder ~ Region
## Model 2: Murder ~ Region + Assault
##   Res.Df    RSS Df Sum of Sq      F    Pr(>F)
## 1     46 538.32
## 2     45 225.12  1    313.19 62.605 4.626e-10 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
# F is about 63, and the p-value is about 5e-10.

# Test whether the Assault slope differs by Region.
anova(reg2_2, reg2_3)
## Analysis of Variance Table
##
## Model 1: Murder ~ Region + Assault
## Model 2: Murder ~ Region * Assault
##   Res.Df    RSS Df Sum of Sq     F Pr(>F)
## 1     45 225.12
## 2     42 212.05  3    13.072 0.863 0.4678
# F is about 0.86, and the p-value is about 0.47.
# So there is little evidence that the slope differs across regions.
Permutation Tests
The theoretical \(F\)-test uses assumptions about independent Normal errors with equal variance. A permutation test instead constructs a null distribution by rearranging the observed factor labels.
A permutation test for a factor variable repeatedly shuffles the factor labels without replacement, recomputes a global statistic such as \(\hat{F}\), and compares the observed statistic with this permutation distribution. Under the null, the labels must be exchangeable across observations.
Permutation tests are useful when we want a reference distribution that preserves the observed outcomes and the exact number of observations in each group. As in Comparing Multiple Groups, sampling without replacement keeps all the group counts fixed.
A Global Factor Test
The global \(F\)-statistic tests the factor as one object. This is preferable to separately permuting its \(G-1\) coded columns, which would destroy the rule that each observation belongs to exactly one group. It is also coding-invariant, so treatment and effect coding produce the same observed and permuted statistics.
Code
## MAIN EXAMPLE
set.seed(23)

F_stat <- function(y_hat, group) {
    reg <- lm(y_hat ~ group)
    F_value <- anova(reg)[['F value']][1]
    return(F_value)
}

F_obs <- F_stat(y_hat=xy_hat[,'wage'], group=xy_hat[,'school_g'])
n_perm <- 9999
F_perm <- rep(NA, n_perm)

for (b in seq(n_perm)) {
    group_b <- sample(xy_hat[,'school_g'], replace=FALSE)
    F_perm[b] <- F_stat(y_hat=xy_hat[,'wage'], group=group_b)
}

# Permutation p-value
p_perm <- mean(F_perm >= F_obs)
p_param <- anova(reg_lm)[['Pr(>F)']][1]
c(F_obs=F_obs, p_permutation=p_perm, p_parametric=p_param)
##         F_obs p_permutation  p_parametric
##  1.280237e+02  0.000000e+00  2.863426e-54
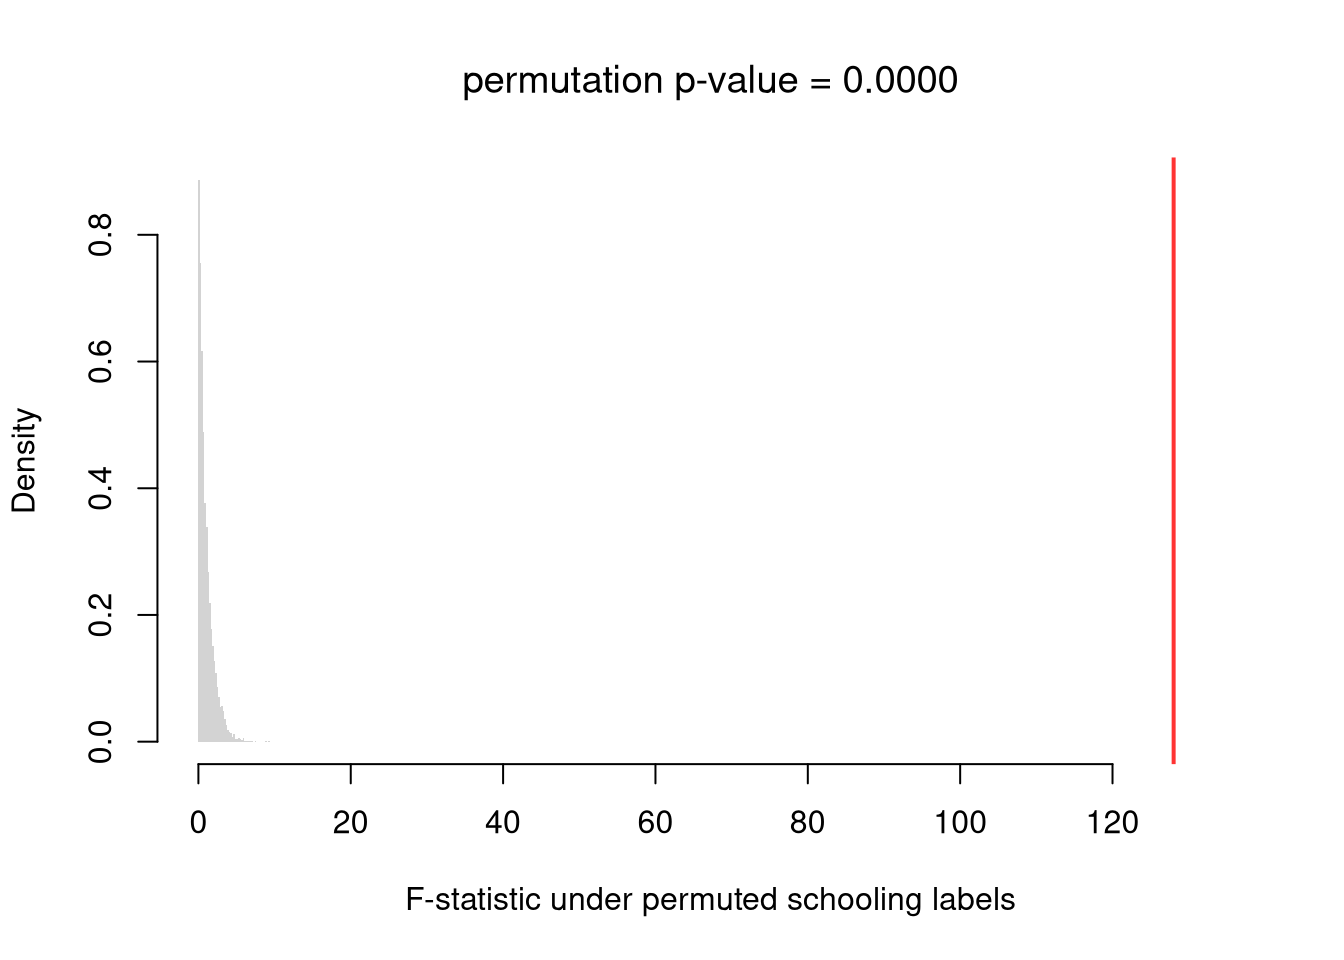
# No shuffle reached the observed F of about 128.
# So p_permutation is 0.
# With 9999 shuffles, that only says the p-value is probably below about 3/9999, or 0.0003.
# A formula has no such limit, so p_parametric can report a far smaller value.

hist(F_perm, breaks=40, border=NA, freq=FALSE, main=NA,
    xlim=c(0, F_obs*1.05),
    xlab='F-statistic under permuted schooling labels')
abline(v=F_obs, col=rgb(1, 0, 0, .8), lwd=2)
title(paste0('permutation p-value = ',
    formatC(p_perm, format='f', digits=4)), font.main=1)
Code
# The observed F sits far to the right of every shuffled F.
# Schooling was not randomly assigned, so this shows association only.
# It does not estimate the effect of moving a worker to another group.
An observed \(F\)-statistic in the far-right tail of the permutation distribution provides evidence that the outcome and the factor are associated, under the assumption that the labels are exchangeable under the null.
Repeat the permutation test with murder arrest rates across the census regions.
Code
# All 50 US states, with the four census regions as a factor.
xy2_hat <- USArrests
xy2_hat$Region <- state.region
reg2_lm <- lm(Murder ~ Region, data=xy2_hat)

F2_obs <- F_stat(y_hat=xy2_hat[,'Murder'], group=xy2_hat[,'Region'])
F2_perm <- rep(NA, n_perm)

for (b in seq(n_perm)) {
    group2_b <- sample(xy2_hat[,'Region'], replace=FALSE)
    F2_perm[b] <- F_stat(y_hat=xy2_hat[,'Murder'], group=group2_b)
}

# Permutation p-value
p2_perm <- mean(F2_perm >= F2_obs)
p2_param <- anova(reg2_lm)[['Pr(>F)']][1]
c(F_obs=F2_obs, p_permutation=p2_perm, p_parametric=p2_param)
##         F_obs p_permutation  p_parametric
##  1.114389e+01  0.000000e+00  1.282093e-05

hist(F2_perm, breaks=40, border=NA, freq=FALSE, main=NA,
    xlim=c(0, F2_obs*1.05),
    xlab='F-statistic under permuted region labels')
abline(v=F2_obs, col=rgb(1, 0, 0, .8), lwd=2)
title(paste0('permutation p-value = ',
    formatC(p2_perm, format='f', digits=4)), font.main=1)
Code
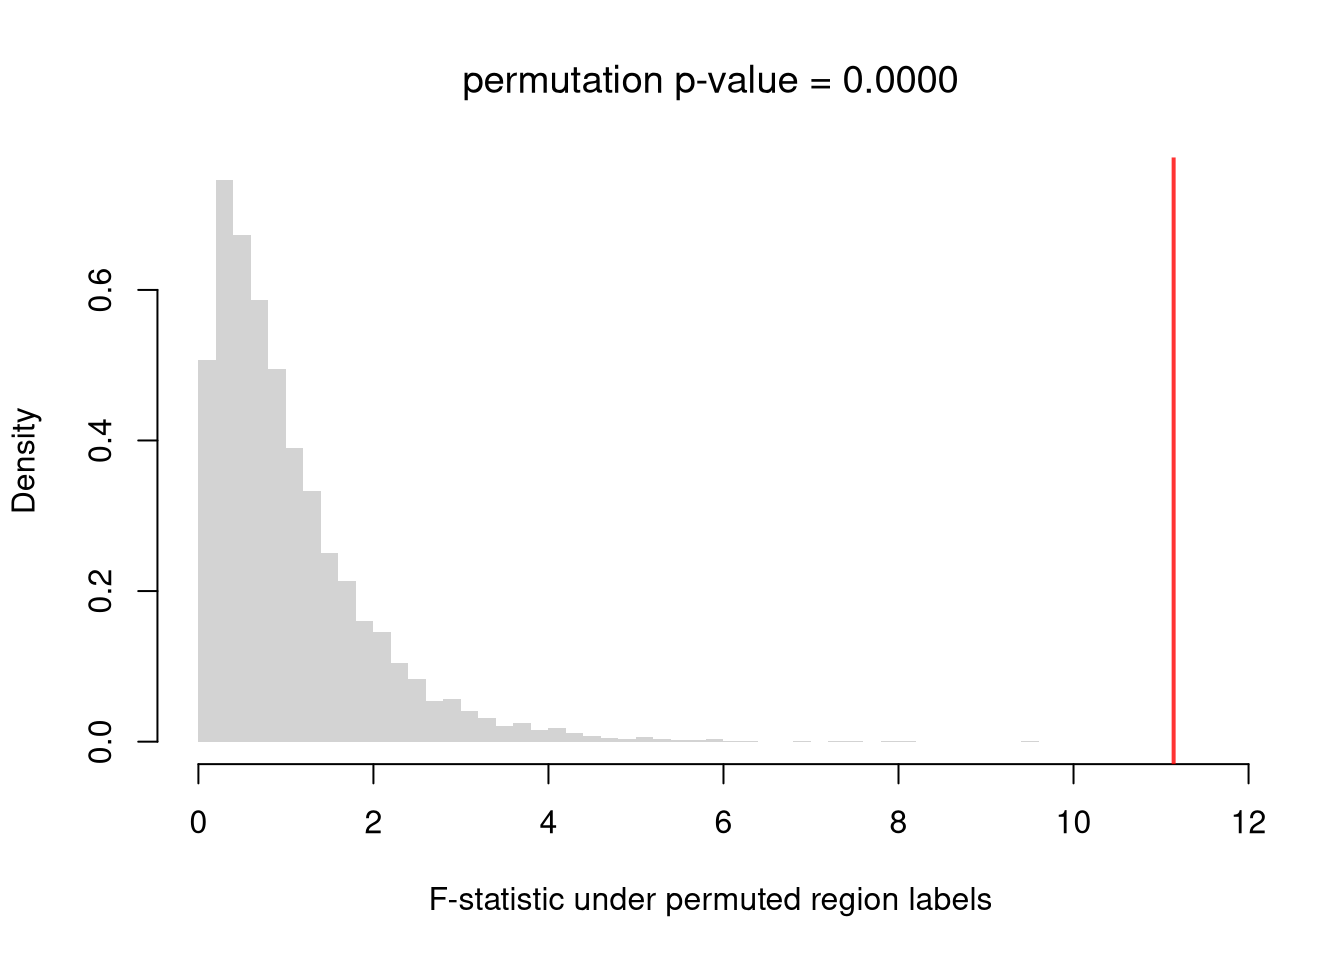
# The observed F of about 11 lies in the far-right tail of the shuffled F's.
# This is evidence that murder arrest rates and region are associated.
# That reading assumes the labels are exchangeable under the null.
# States may be spatially related, and region was not randomly assigned.
# The p-value does not estimate the effect of moving a state to another region.
What Can Be Permuted
The simple shuffle above is appropriate for the factor-only model because the null removes the only relationship in the model. In a regression with controls, naively shuffling the factor would also break its relationship with those controls. Adjusted permutation tests therefore require a design-specific restricted permutation or a method that permutes residuals under a reduced model.
Exchangeability is also an assumption about the data, which the shuffle itself cannot check. Observations may be related to one another, and the factor may not have been randomly assigned. A small permutation \(p\)-value does not estimate the effect of moving an observation to another group.
A permutation test changes the pairing between the outcome and the factor while preserving the group counts. If the factor had been randomly assigned in an experiment, the shuffle could reproduce the assignment mechanism. For observational data, it instead tests a no-association null under exchangeability.
Subsampling
Permutation and subsampling both rerun a statistic on altered data, but they answer different questions. Permutation breaks a relationship to impose a null. Subsampling preserves each row and asks how much an estimate changes when some rows are left out.
Random subsampling draws \(B\) samples of size \(m<n\) without replacement and recomputes the statistic in each. When \(m=n-d\), the procedure is a random delete-\(d\) jackknife.
Random subsampling is useful for checking whether a regression result is stable across overlapping subsets of the observed data. The table compares it with the bootstrap and jackknife.
Bootstrap, Jackknife, and Subsampling
| Bootstrap |
\(n\) |
\(B\) |
With replacement |
| Jackknife |
\(n-1\) |
\(n\) |
Without replacement |
| Random delete-\(d\) subsample |
\(m=n-d\) |
\(B\) |
Without replacement |
Random Delete-\(d\) Samples
The raw spread of estimates across overlapping subsamples is not the standard error of the full-sample estimator. For the random delete-\(d\) jackknife used here, the variance estimate applies the correction (Politis et al. 1999) \[
\hat{v}^{\text{sub}}
=
\frac{m}{dB}
\sum_{b=1}^{B}
\left(\hat{b}^{\text{sub}}_{b}-\hat{b}^{\text{sub}}\right)^2,
\] where \(\hat{b}^{\text{sub}}\) is the mean of the \(\hat{b}^{\text{sub}}_{b}\), and \(\hat{\text{SE}}^{\text{sub}}=\sqrt{\hat{v}^{\text{sub}}}\). The example uses a Normal approximation around the full-sample coefficient rather than taking raw percentiles of the overlapping subsample estimates.
Code
## MAIN EXAMPLE
reg <- lm(wage ~ school, data=xy_hat)
b_full <- coef(reg)['school']

# Draw random delete-d samples without replacement.
# Each draw deletes about a fifth of the 3294 workers: d=659 and m=2635.
n <- nrow(xy_hat)
d <- round(n/5)
m <- n - d
n_sub <- 999
rs_coefs <- rep(NA, n_sub)

for (b in seq(n_sub)) {
    b_id <- sample(n, m, replace=FALSE)
    xy_sub <- xy_hat[b_id,]
    reg_b <- lm(wage ~ school, data=xy_sub)
    rs_coefs[b] <- coef(reg_b)['school']
}

# Correct the spread for overlapping delete-d samples.
# Here m/d is about 4, so the correction about doubles the raw spread.
rs_mean <- mean(rs_coefs)
rs_var <- (m/d)*mean((rs_coefs - rs_mean)^2)
rs_se <- sqrt(rs_var)
rs_ci <- b_full + qnorm(c(.025, .975))*rs_se
c(b_full=b_full, subsample_SE=rs_se, lower=rs_ci[1], upper=rs_ci[2])
## b_full.school  subsample_SE         lower         upper
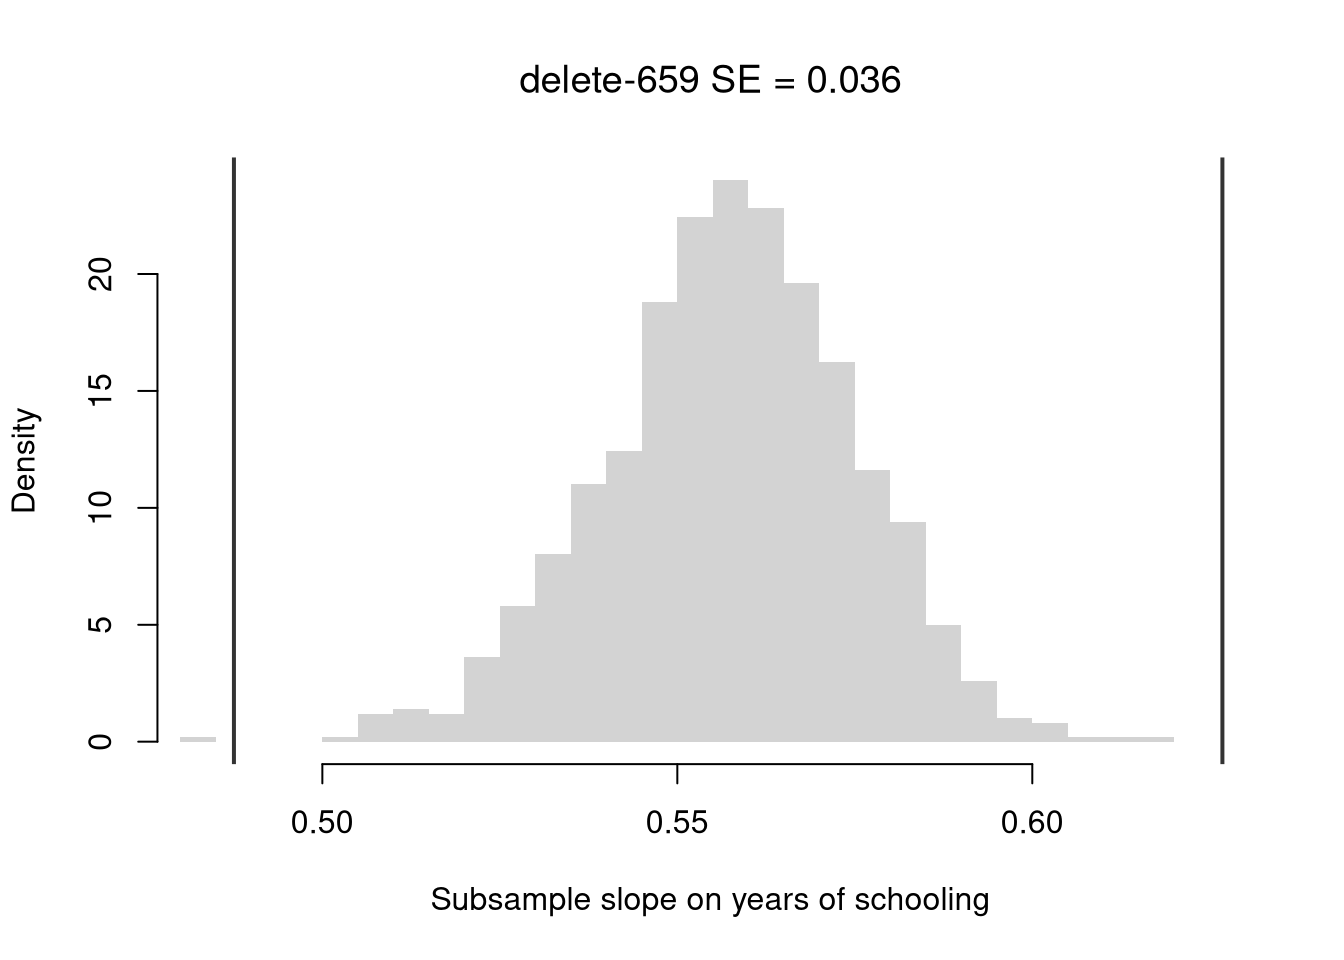
##    0.55716169    0.03551907    0.48754560    0.62677779
# Each year of schooling goes with about 0.56 dollars more per hour.
# The subsample SE is about 0.036.
# The interval runs from about 0.49 to 0.63, well above zero.

hist(rs_coefs, breaks=25, border=NA, freq=FALSE, main=NA,
    xlim=range(c(rs_coefs, rs_ci)),
    xlab='Subsample slope on years of schooling')
abline(v=rs_ci, col=rgb(0, 0, 0, .8), lwd=2)
title(paste0('delete-', d, ' SE = ', round(rs_se, 3)), font.main=1)
Code
# Nearly all raw slopes sit inside the interval, since the subsamples overlap.
The example deletes \(d\) observations and retains \(m=n-d\) per iteration. Increasing \(d\) makes individual subsets less similar to the full dataset, while increasing \(B\) only reduces Monte Carlo noise from which subsets happened to be drawn. Neither change creates new information beyond the original \(n\) observations.
Repeat the delete-\(d\) standard error for the slope of murder arrest rates on urban population across the states.
Code
# All 50 US states, with percent urban population in the column UrbanPop.
xy2_hat <- USArrests
reg2_full <- lm(Murder ~ UrbanPop, data=xy2_hat)
b2_full <- coef(reg2_full)['UrbanPop']

# Draw random delete-10 samples without replacement, so m=40 states remain.
n2 <- nrow(xy2_hat)
d2 <- 10
m2 <- n2 - d2
n2_sub <- 999
rs2_coefs <- rep(NA, n2_sub)

for (b in seq(n2_sub)) {
    b_id <- sample(n2, m2, replace=FALSE)
    xy2_sub <- xy2_hat[b_id,]
    reg2_b <- lm(Murder ~ UrbanPop, data=xy2_sub)
    rs2_coefs[b] <- coef(reg2_b)['UrbanPop']
}

# Correct the spread for overlapping delete-d samples.
rs2_mean <- mean(rs2_coefs)
rs2_var <- (m2/d2)*mean((rs2_coefs - rs2_mean)^2)
rs2_se <- sqrt(rs2_var)
rs2_ci <- b2_full + qnorm(c(.025, .975))*rs2_se
c(b_full=b2_full, subsample_SE=rs2_se, lower=rs2_ci[1], upper=rs2_ci[2])
## b_full.UrbanPop    subsample_SE           lower           upper
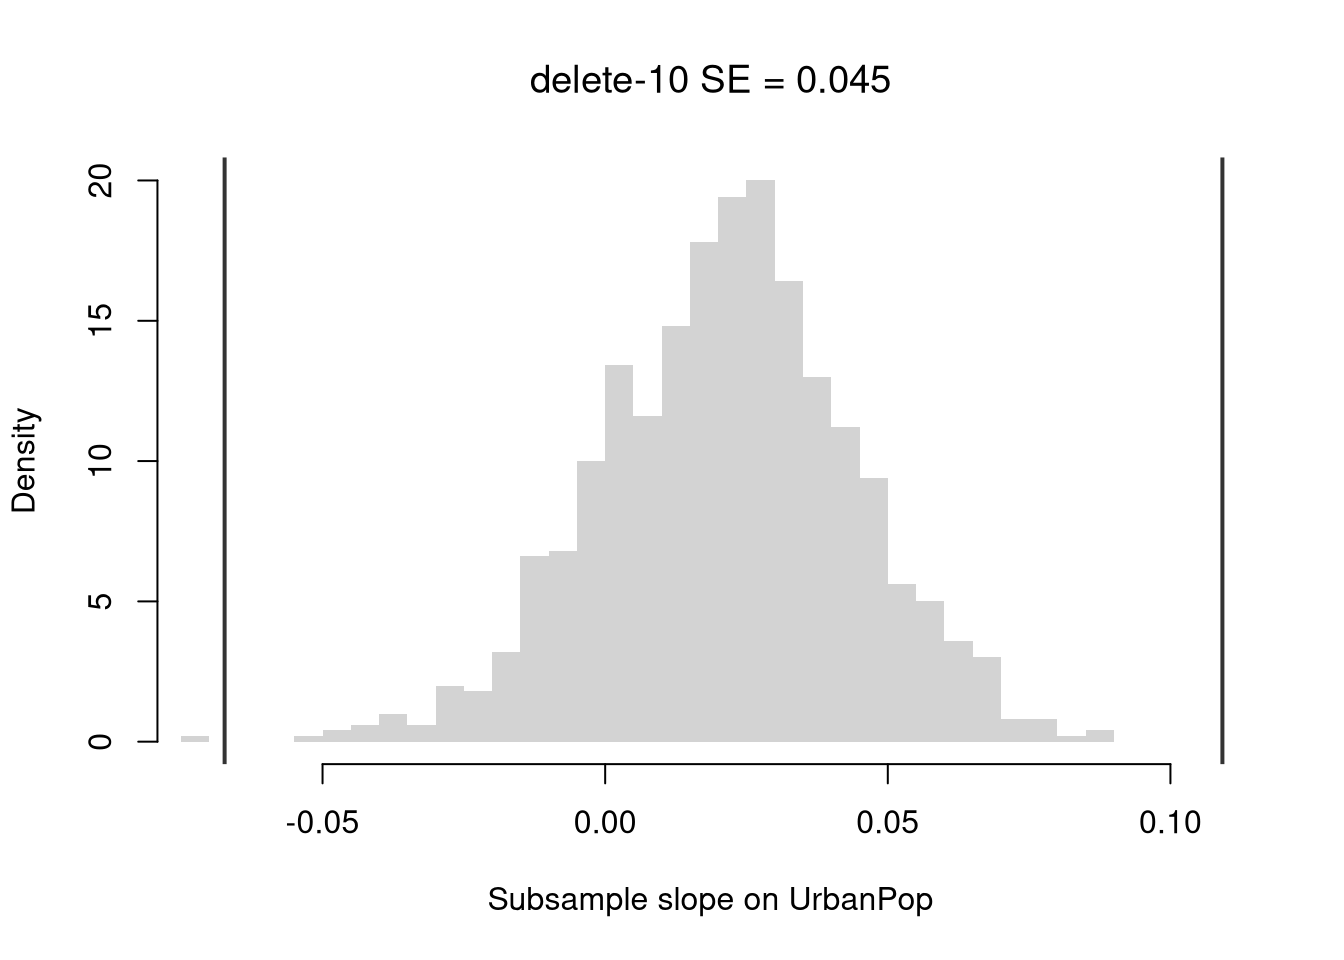
##      0.02093466      0.04503122     -0.06732491      0.10919422
# The slope is about 0.02, and the subsample SE is about 0.045.
# The interval runs from about -0.07 to 0.11, so it includes zero.

hist(rs2_coefs, breaks=25, border=NA, freq=FALSE, main=NA,
    xlim=range(c(rs2_coefs, rs2_ci)),
    xlab='Subsample slope on UrbanPop')
abline(v=rs2_ci, col=rgb(0, 0, 0, .8), lwd=2)
title(paste0('delete-', d2, ' SE = ', round(rs2_se, 3)), font.main=1)
Subsampling also extends to strongly dependent data, including spatial data (Politis and Romano 1994; Sherman 1996; Politis et al. 1999; Choi and Chue 2007; Adamson 2025). The related m-out-of-n bootstrap draws resamples of size \(m<n\) with replacement (Fukuchi 1994; Bickel et al. 1997; Bickel and Sakov 2008; Adamson 2020).
Jackknife Percentile Intervals
Can we rescale the subsample estimates themselves and then take their percentiles, as in Confidence Intervals? Wu (1986, 1270–71) develops a jackknife percentile method that does this with delete-\(d\) samples. For the sample mean, let \(\hat{m}\) be the full-sample mean and \(\hat{m}^{\text{sub}}_{b}\) the mean of subsample \(b\), which retains \(m=n-d\) observations. The rescaled value is \[
\hat{m}^{\text{scaled}}_{b} = \hat{m} + \sqrt{\frac{m}{d}}\left(\hat{m}^{\text{sub}}_{b} - \hat{m}\right).
\] We can take the \(2.5\)th and \(97.5\)th percentiles of these values to construct an approximate \(95\%\) interval for the population mean. For independent observations from the same nonnormal distribution with finite, positive variance, both the number retained and the number deleted must grow with \(n\) for the rescaled mean histogram to approach a Normal distribution. Keeping \(d=1\), or any other fixed number, does not generally satisfy this condition.
Retain half of the workers in each subsample and estimate the mean hourly wage. With \(m=d\), the rescaling factor is \(\sqrt{m/d}=1\). Sampling without replacement reduces the variation across these overlapping half-samples enough that their spread already estimates the uncertainty in the full-sample mean.
Code
# Use half-samples to construct a percentile interval for the mean.
x_hat <- xy_hat[, 'wage']
m_hat <- mean(x_hat)
n <- length(x_hat)
# Half of the 3294 workers: 1647 retained and 1647 deleted.
n_keep <- floor(n / 2)
n_delete <- n - n_keep
n_sub <- 9999
sub_means <- rep(NA, n_sub)

for (b in seq(n_sub)) {
    x_sub <- sample(x_hat, n_keep, replace=FALSE)
    sub_means[b] <- mean(x_sub)
}

# Put the subsample deviations on the full-sample scale.
scaled_means <- m_hat + sqrt(n_keep / n_delete) * (sub_means - m_hat)
ci_percentile <- quantile(scaled_means, probs=c(.025, .975))
ci_normal <- m_hat + qnorm(c(.025, .975)) * sd(x_hat) / sqrt(n)
round(rbind(percentile=ci_percentile, normal=ci_normal), 3)
##             2.5% 97.5%
## percentile 5.646 5.871
## normal     5.646 5.869
# Both intervals run from about 5.65 to 5.87 dollars.
The confidence-interval interpretation treats the observations as independent draws from a common population distribution. The interval has a large-sample justification, not a guarantee of exactly \(95\%\) coverage in a finite sample. Wu also reports undercoverage in some finite-sample examples.
Repeat the half-sample interval with murder arrest rates across the states. How close are the percentile and Normal intervals?
Code
# Use half-samples to construct a percentile interval for the mean.
x2_hat <- USArrests[, 'Murder'] # murder arrests per 100,000
m2_hat <- mean(x2_hat)
n2 <- length(x2_hat)
# Half of the 50 states: 25 retained and 25 deleted.
n2_keep <- floor(n2 / 2)
n2_delete <- n2 - n2_keep
n2_sub <- 9999
sub2_means <- rep(NA, n2_sub)

for (b in seq(n2_sub)) {
    x2_sub <- sample(x2_hat, n2_keep, replace=FALSE)
    sub2_means[b] <- mean(x2_sub)
}

# Put the subsample deviations on the full-sample scale.
scaled2_means <- m2_hat + sqrt(n2_keep / n2_delete) * (sub2_means - m2_hat)
ci2_percentile <- quantile(scaled2_means, probs=c(.025, .975))
ci2_normal <- m2_hat + qnorm(c(.025, .975)) * sd(x2_hat) / sqrt(n2)
round(rbind(percentile=ci2_percentile, normal=ci2_normal), 3)
##             2.5% 97.5%
## percentile 6.568 8.996
## normal     6.581 8.995
# Both intervals run from about 6.6 to 9.0 arrests per 100,000.
# This treats the state rates as independent draws from a common population.
# With 50 observations, coverage need not be exactly 95%.
For regression coefficients, Wu’s method also uses weights based on the subset design matrices and a scale factor that accounts for the number of coefficients. The mean example above is the simpler special case, so its formula alone does not reproduce Wu’s regression percentile method.
Why Leave-One-Out Percentiles Can Fail
Rescaling the ordinary leave-one-out estimates can match the variance without matching the shape of the sampling distribution. Efron and Tibshirani (1993, 143–44) illustrate an inflated jackknife histogram by multiplying deviations from the average jackknife estimate by \(\sqrt{n-1}\). Their example compares its spread with a bootstrap histogram; it does not establish that its percentiles give valid confidence limits. For the sample mean, their transformation is \[
\hat{m}^{\text{scaled}(-i)} = \hat{m}^{\text{jack}} + \sqrt{n-1}\left(\hat{m}^{(-i)} - \hat{m}^{\text{jack}}\right),
\] where \(\hat{m}^{\text{jack}}\) is the average of the leave-one-out means. The variance of these rescaled values, computed with divisor \(n\), equals the usual jackknife variance estimate. However, since \(\hat{m}^{\text{jack}}=\hat{m}\), we can rewrite the transformation as \[\begin{aligned}
\hat{m}^{(-i)} &= \frac{n\hat{m} - \hat{x}_{i}}{n-1} \\
\hat{m}^{\text{scaled}(-i)} &= \hat{m} + \frac{\hat{m} - \hat{x}_{i}}{\sqrt{n-1}}.
\end{aligned}\] These rescaled values retain the reflected shape of the individual observations, while the sampling distribution of the sample mean approaches a Normal distribution under the assumptions above. Matching the variance therefore does not generally match the percentiles.
Suppose customer waiting times are independent Exponential random variables with rate \(1\), so their population mean and variance both equal \(1\). For the inflated leave-one-out interval above, the limiting coverage is the Normal probability between the Exponential population quantiles minus \(1\).
Code
# Compute limiting coverage rather than simulate repeated samples.
exp_quantiles <- qexp(c(.025, .975), rate=1)
coverage_limit <- diff(pnorm(exp_quantiles - 1))
coverage_limit # about 0.832, despite a nominal coverage of 0.95
## [1] 0.8315564
Increasing the sample size does not repair this mismatch: the nominal \(95\%\) interval approaches about \(83.2\%\) coverage.
Medians and other sample quantiles have an additional difficulty: the ordinary delete-one jackknife can give inconsistent variance estimates (Martin 1990). For smooth statistics, the ordinary jackknife remains useful for estimating standard errors to use in a Normal approximation. Percentile intervals instead require a suitable bootstrap or a justified delete-\(d\) procedure; simply stretching the leave-one-out values is not enough.
Permutation Versus Subsampling
A permutation iteration keeps all \(n\) observations but changes which outcome is paired with each factor label. A subsampling iteration keeps the original pairings but uses only \(m<n\) observations. The permutation distribution describes a test statistic under a null relationship. The subsampling distribution describes sensitivity to omitting observations and requires a scaling correction before it estimates full-sample uncertainty.
What the Results Establish
Treatment coding and effect coding are two coordinate systems for the same fitted group means.
A small permutation \(p\)-value provides evidence against a no-association null under exchangeability. It shows that the observed pairing of outcomes and labels is unusual. It does not show what would happen under an intervention.
The subsampling result shows how a coefficient responds to deleting observations. A stable coefficient can still be confounded, and an unstable coefficient is not necessarily biased.
These limits extend the distinction introduced in Association is not Causation.
Exercises
Comment the script you wrote for this chapter, then restart R and check that it runs from a clean session, then check the script with AI as explained in Working with AI. Write three sentences from memory on the main statistical idea of this chapter, and ask the assistant what is wrong, vague, or missing. Finish with your own questions about whatever you found hardest.
Suppose three groups have means \(4\), \(7\), and \(5\). Compute the treatment-coded coefficients using the first group as the reference. Then compute the effect-coded intercept and all three group effects, checking that the effects sum to zero.
Store USArrests with a Region column from state.region as xy2_hat, then construct a permutation test of whether mean Assault arrest rates differ across regions. Use \(B=9999\) permutations, report the global \(F\)-statistic and permutation \(p\)-value, and compare the result with anova(lm(Assault ~ Region, data=xy2_hat)).
Extend the running example by fitting wage ~ school_g + exper + sex and wage ~ school_g * exper + sex. Use anova() to test whether the school_g-exper interaction terms are jointly significant after controlling for sex. Explain why this test does not establish that experience causes higher wages.
Repeat the subsampling example with \(d\) equal to about \(10\%\), \(20\%\), and \(40\%\) of the observations. Apply the delete-\(d\) correction in each case and compare the standard errors. Explain why increasing \(B\) makes the simulation more stable without increasing the information in the original sample.
Further Reading
- https://www.econometrics-with-r.org/7-htaciimr.html – hypothesis tests for comparing groups in a regression framework, including \(F\)-tests and joint restrictions.
- https://online.stat.psu.edu/stat462/node/137/ – ANOVA as a special case of regression, with examples of multiple-group comparisons.
- Politis et al. (1999) – a systematic treatment of subsampling methods and their statistical foundations.
- De Bin et al. (2015) – a comparison of subsampling and bootstrapping for the stability of multivariable regression models.
- Wu (1986) – jackknife percentile intervals from rescaled delete-\(d\) estimates, including a weighted regression method.
- Efron and Tibshirani (1993) – inflated jackknife histograms and their relationship to bootstrap variability.
- Martin (1990) – why the ordinary jackknife can fail for sample quantiles.
Recall
This chapter rewrote ANOVA as a regression with a factor variable and showed that treatment and effect coding change coefficient meanings without changing the fitted model. The schooling example gave an effect-coded intercept of about \(5.98\), the unweighted mean of the three group means, while its global \(F\)-statistic was identical under both codings. With a fixed effect for each schooling group, a year of experience went with about \(0.10\) dollars more per hour, and the schooling gaps barely moved. Nested-model \(F\)-tests asked whether each added layer adds information, and all three rejected the simpler model. The permutation test shuffled the factor labels to test a no-association null, whereas random delete-\(d\) subsampling preserved each row and measured sensitivity to omitted observations.
Adamson, Jordan. 2020.
“Political Institutions, Resources, and War: Theory and Evidence from Ancient Rome.” Explorations in Economic History 76: 101324.
https://doi.org/10.1016/j.eeh.2020.101324.
Adamson, Jordan. 2025.
“Trade and the Rise of Ancient Greek City-States.” Journal of Economic Behavior & Organization 235: 107035.
https://doi.org/10.1016/j.jebo.2025.107035.
Balli, Hatice Ozer, and Bent E. Sørensen. 2013.
“Interaction Effects in Econometrics.” Empirical Economics 45 (1): 583–603.
https://doi.org/10.1007/s00181-012-0604-2.
Bickel, P. J., F. Götze, and W. R. van Zwet. 1997. “Resampling Fewer Than n Observations: Gains, Losses, and Remedies for Losses.” Statistica Sinica 7 (1): 1–31.
Bickel, Peter J., and Anat Sakov. 2008.
“On the Choice of m in the m Out of n Bootstrap and Confidence Bounds for Extrema.” Statistica Sinica 18 (3): 967–85.
http://www.jstor.org/stable/24308525.
Brambor, Thomas, William Roberts Clark, and Matt Golder. 2006.
“Understanding Interaction Models: Improving Empirical Analyses.” Political Analysis 14 (1): 63–82.
https://doi.org/10.1093/pan/mpi014.
Choi, In, and Timothy K. Chue. 2007.
“Subsampling Hypothesis Tests for Nonstationary Panels with Applications to Exchange Rates and Stock Prices.” Journal of Applied Econometrics 22 (2): 233–64.
http://www.jstor.org/stable/25146516.
De Bin, Riccardo, Silke Janitza, Willi Sauerbrei, and Anne-Laure Boulesteix. 2015.
“Subsampling Versus Bootstrapping in Resampling-Based Model Selection for Multivariable Regression.” Biometrics 72 (1): 272–80.
https://doi.org/10.1111/biom.12381.
Efron, Bradley, and Robert J. Tibshirani. 1993.
An Introduction to the Bootstrap. Vol. 57. Monographs on Statistics and Applied Probability. Chapman & Hall.
https://doi.org/10.1007/978-1-4899-4541-9.
Fukuchi, Jun-ichiro. 1994.
“Bootstrapping Extremes of Random Variables.” {Ph.D.} dissertation, Iowa State University.
https://doi.org/10.31274/rtd-180813-10322.
Martin, Michael A. 1990.
“On Using the Jackknife to Estimate Quantile Variance.” Canadian Journal of Statistics 18 (2): 149–53.
https://doi.org/10.2307/3315563.
Mundlak, Yair. 1978.
“On the Pooling of Time Series and Cross Section Data.” Econometrica 46 (1): 69–85.
https://doi.org/10.2307/1913646.
Politis, D. N., J. P. Romano, M. Wolf, P. Diggle, and S. Fienberg. 1999.
Subsampling. Springer Series in Statistics. Springer New York.
https://books.google.de/books?id=nGu6rqjE6JoC.
Politis, Dimitris N., and Joseph P. Romano. 1994.
“Large Sample Confidence Regions Based on Subsamples Under Minimal Assumptions.” The Annals of Statistics 22 (4): 2031–50.
https://doi.org/10.1214/aos/1176325770.
Sherman, Michael. 1996.
“Variance Estimation for Statistics Computed from Spatial Lattice Data.” Journal of the Royal Statistical Society: Series B (Methodological) 58 (3): 509–23.
https://doi.org/10.1111/j.2517-6161.1996.tb02097.x.
Wooldridge, Jeffrey M. 2010. Econometric Analysis of Cross Section and Panel Data. 2nd ed. MIT press.
Wu, C. F. J. 1986.
“Jackknife, Bootstrap and Other Resampling Methods in Regression Analysis.” The Annals of Statistics 14 (4): 1261–95.
https://doi.org/10.1214/aos/1176350142.