Code
# Fit a multiple regression and produce the four standard diagnostic plots.
xy_hat <- USArrests
reg <- lm(Murder ~ Assault+UrbanPop, data=xy_hat)
par(mfrow=c(2, 2))
plot(reg, pch=16, col=grey(0, .5))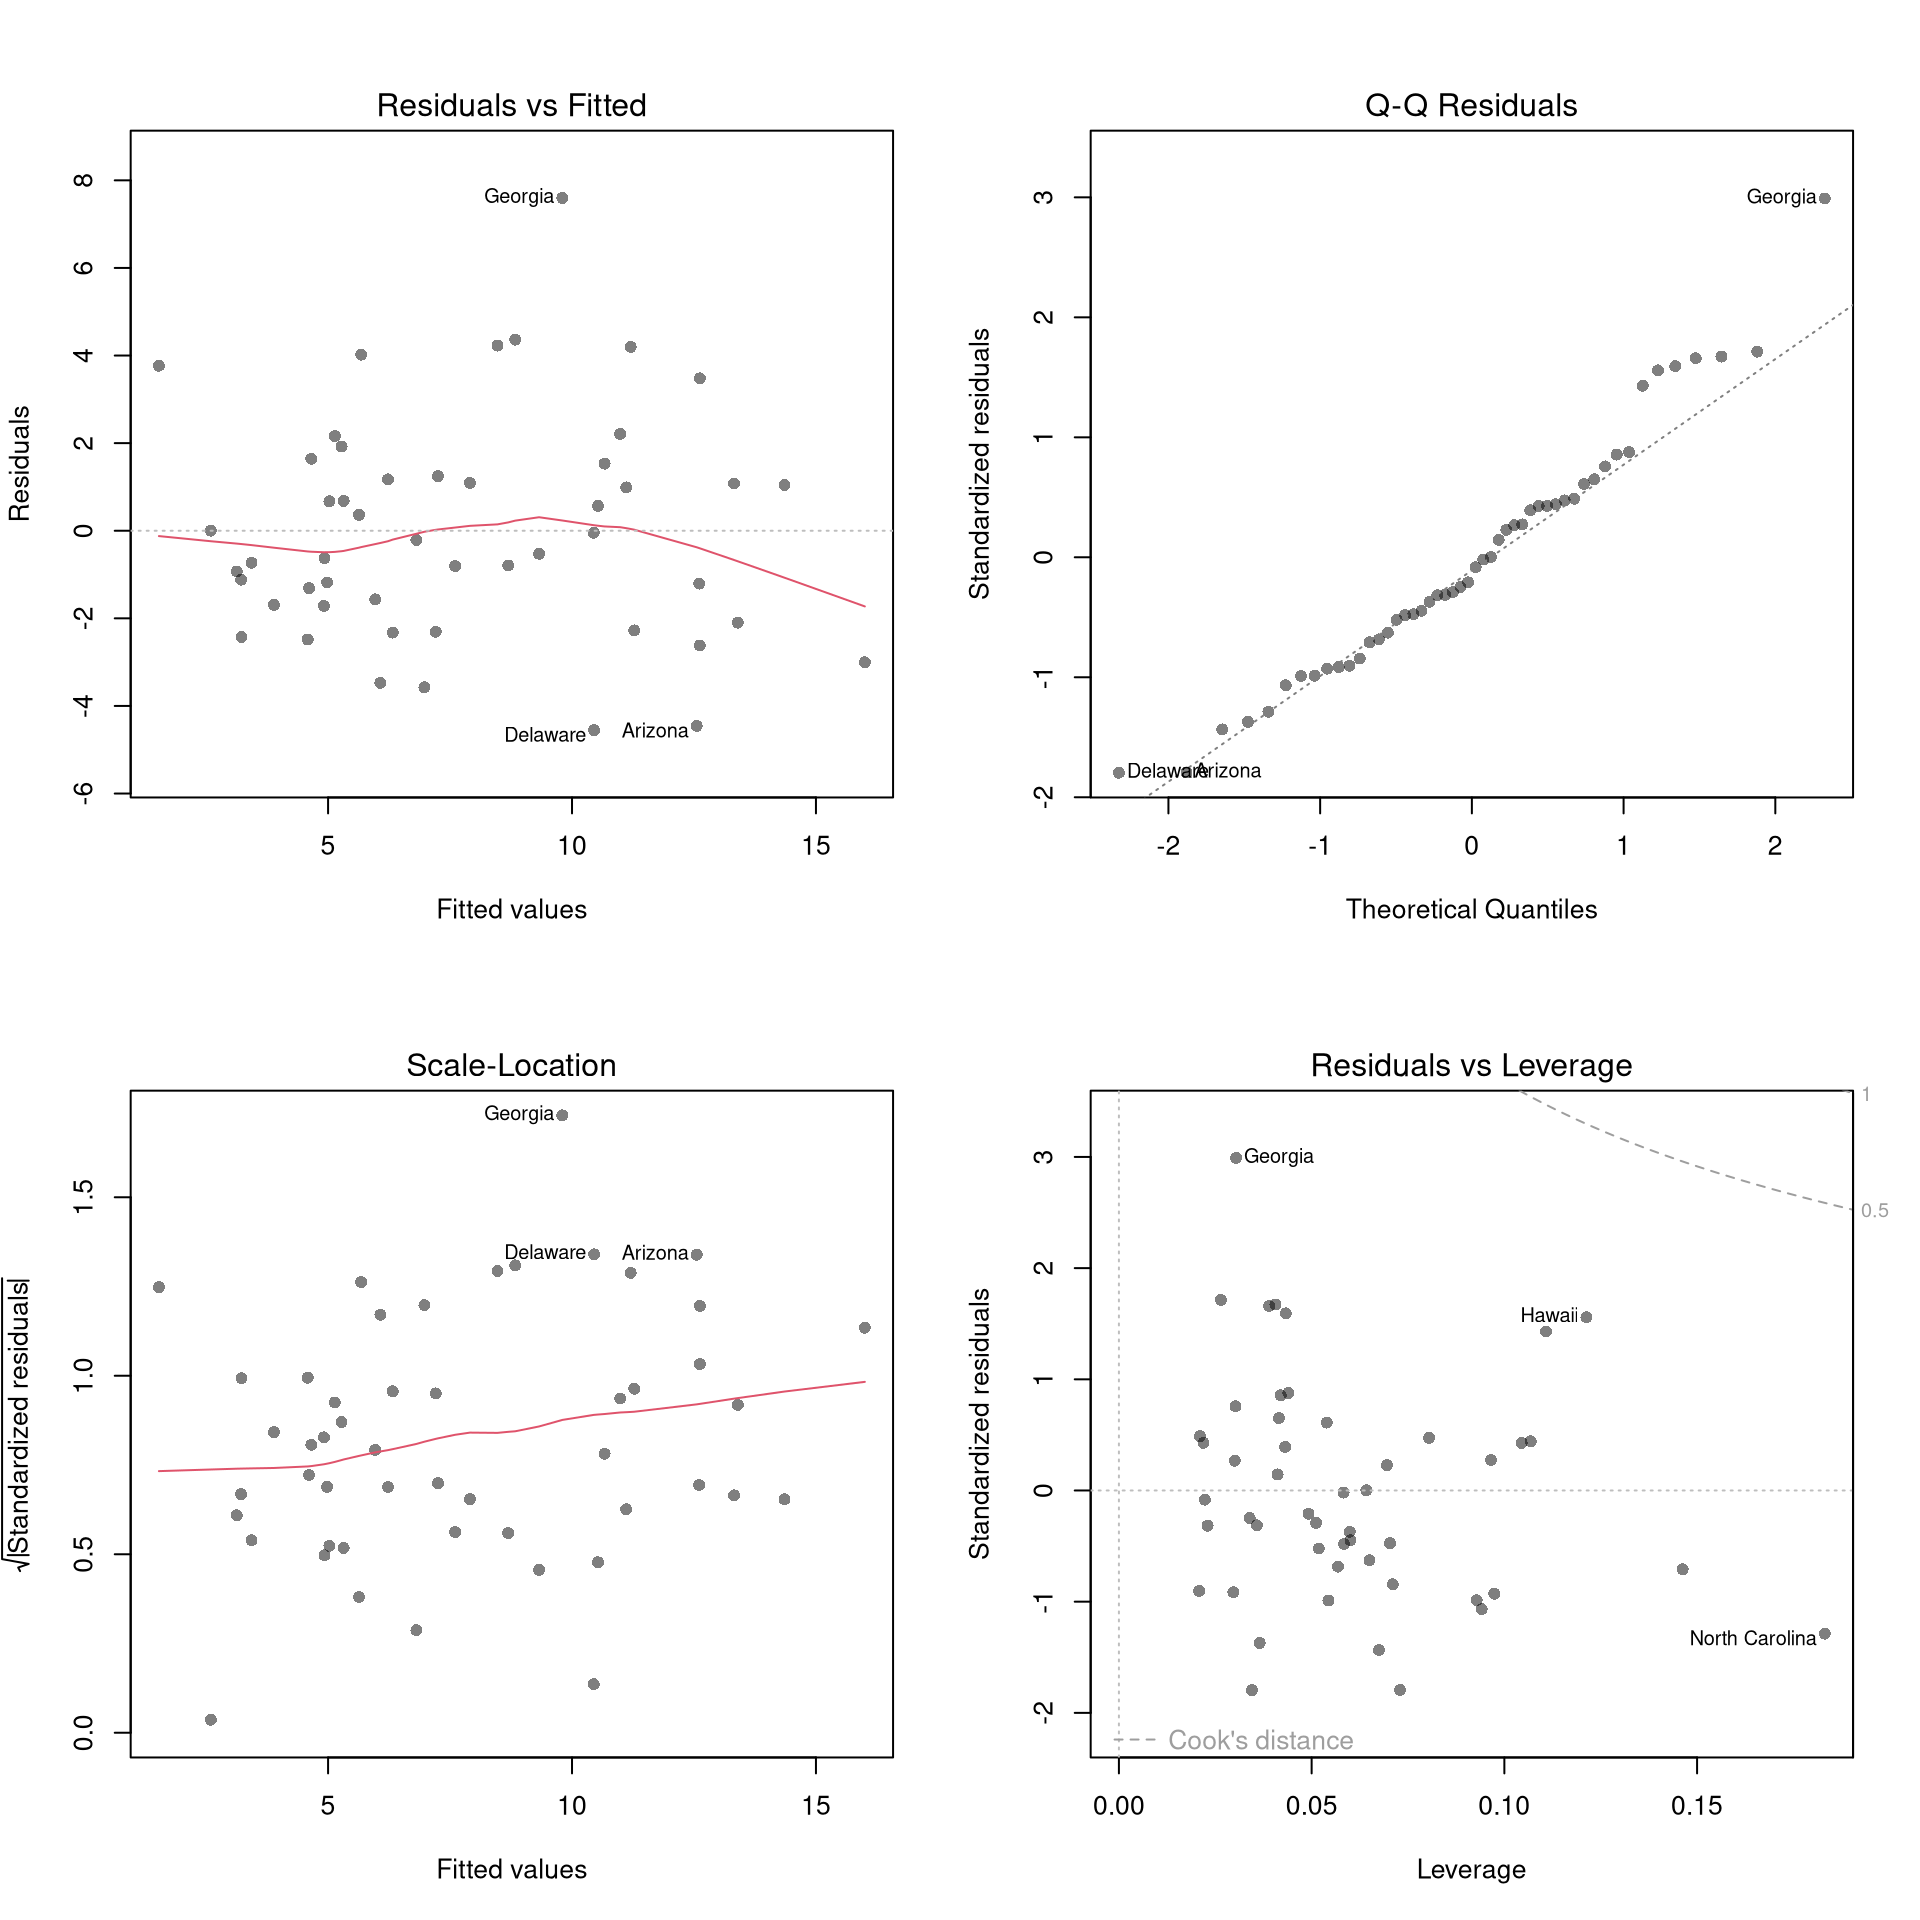
A fitted regression should be audited before its coefficients are reported. This chapter walks through that audit in two stages: the four standard diagnostic plots for outliers, collinearity, and residual structure, and then data transformations that can sometimes rescue a misspecified model. Before either stage, look at the raw data with the scatterplot matrices and conditioning plots from Multivariate Distributions: nonlinear patterns, outliers, and explanatory variables that carry almost the same information are often visible before any model is fit.
There’s little sense in getting great standard errors for a terrible model. Plotting your regression object is a simple and easy step to help diagnose whether your model is in some way bad. Calling plot() on an lm object returns four standard plots: (1) residuals vs fitted, (2) Q-Q normal of residuals, (3) scale-location, and (4) residuals vs leverage with Cook’s distance contours. We next go through what each shows.
# Fit a multiple regression and produce the four standard diagnostic plots.
xy_hat <- USArrests
reg <- lm(Murder ~ Assault+UrbanPop, data=xy_hat)
par(mfrow=c(2, 2))
plot(reg, pch=16, col=grey(0, .5))
Some observations sit far from the rest of the data. Eyeballing the plot will not tell us which ones actually move the fit, so we need quantitative tools.
These three statistics are useful for triage: leverage flags points whose \(\hat{x}_i\) is unusual, the standardized residual flags points whose \(\hat{y}_i\) is far from prediction, and Cook’s Distance combines both into one number that says how much the overall fit depends on each observation. The first diagnostic plot (residuals vs fitted) is the picture for outliers in the outcome, and the fourth (residuals vs leverage with Cook’s contours) is the picture for outliers in \(X\)-space; both can but do not have to be problematic.
N <- 40
x_sim <- c(25, runif(N-1, 3, 8))
e <- rnorm(N, 0, 0.4)
y_sim <- 3 + 0.6*sqrt(x_sim) + e
plot(y_sim ~ x_sim, pch=16, col=grey(0, .5), main=NA)
points(x_sim[1], y_sim[1], pch=16, col=rgb(1, 0, 0, .5))

abline(lm(y_sim ~ x_sim), col=rgb(1, 0, 0, .8), lty=2)
abline(lm(y_sim[-1] ~ x_sim[-1]))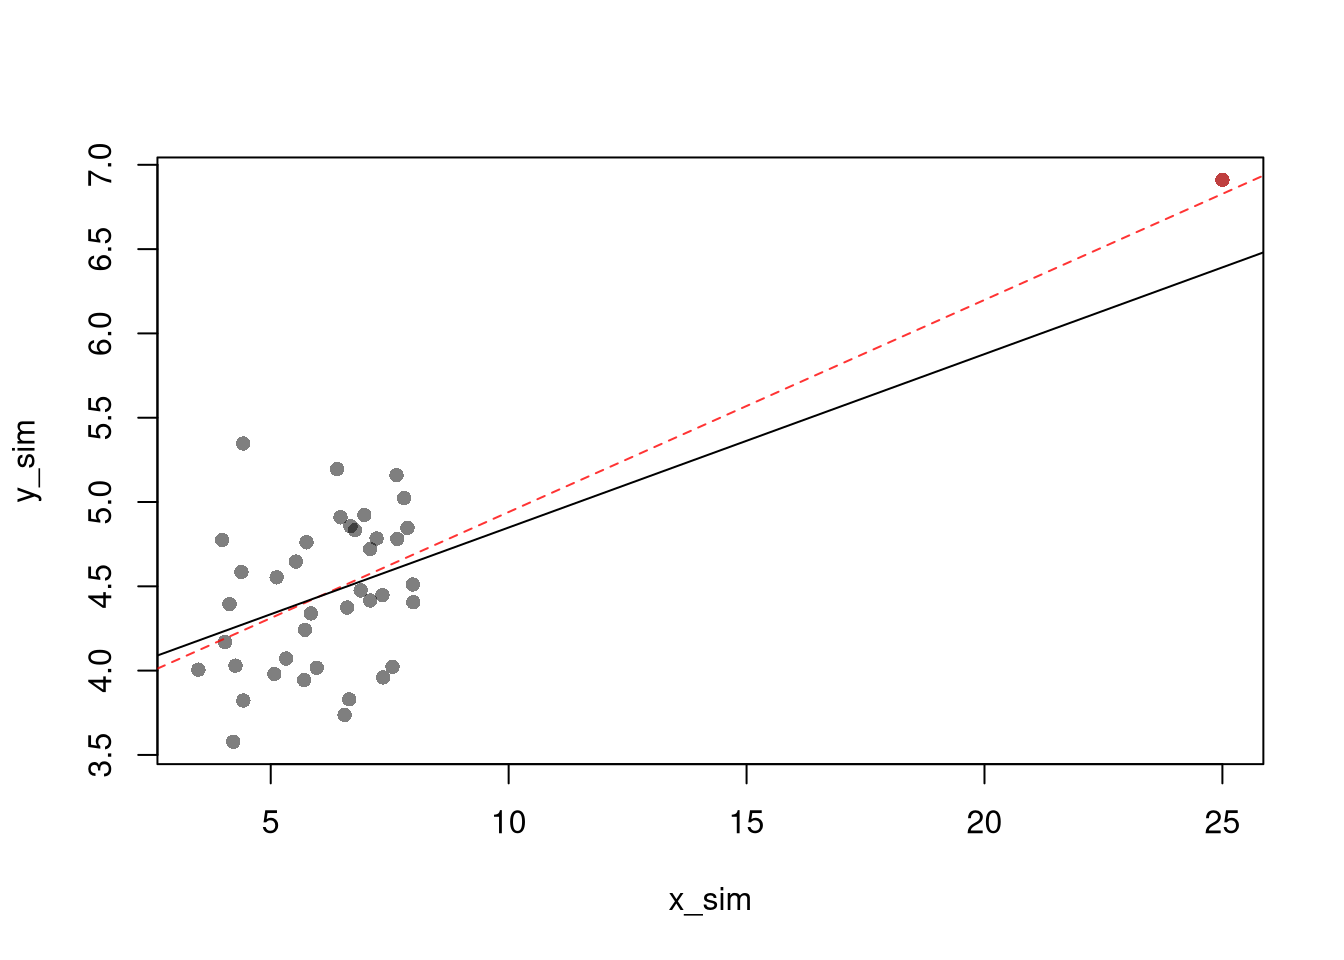
# State with the highest leverage
which.max(hatvalues(reg))
## North Carolina
##             33
# State with the largest standardized residual
which.max(rstandard(reg))
## Georgia
## 10# State with the largest Cook's Distance
which.max(cooks.distance(reg))
## North Carolina
## 33
# Influence plot: leverage vs. standardized residual,
# with point area proportional to Cook's Distance
h_i <- hatvalues(reg)
e_std_hat <- rstandard(reg)
d_i <- cooks.distance(reg)
plot(h_i, e_std_hat, pch=16, col=grey(0, .5),
cex=1 + 4*d_i/max(d_i), main=NA,
xlab='Leverage', ylab='Standardized residual')
abline(h=0, lty=2)
# Label the most influential observations
inf_id <- order(d_i, decreasing=TRUE)[1:3]
text(h_i[inf_id], e_std_hat[inf_id],
labels=rownames(xy_hat)[inf_id], pos=3, cex=.7)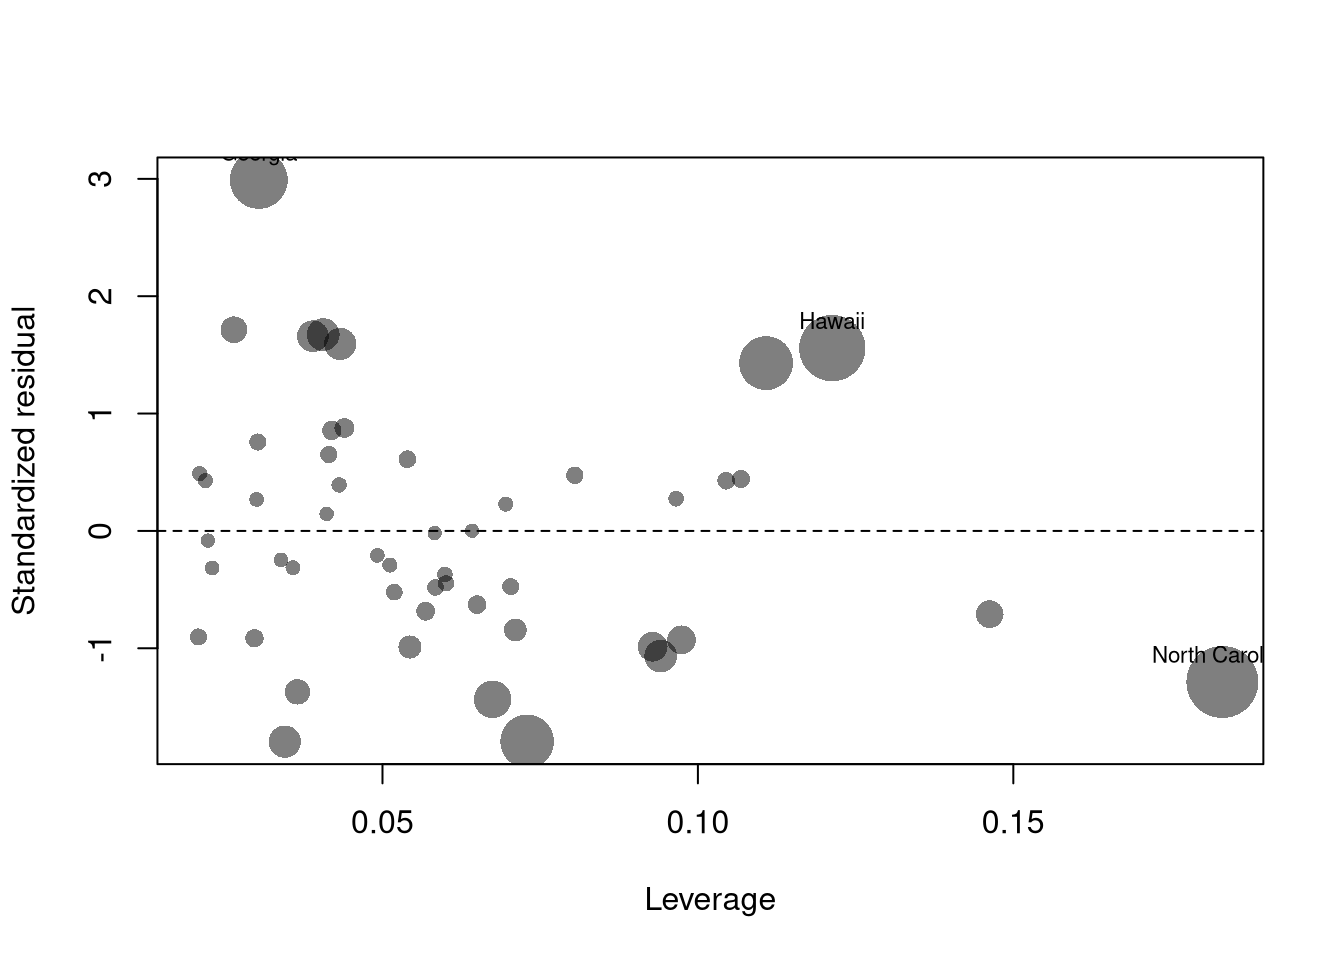
See https://www.r-bloggers.com/2016/06/leverage-and-influence-in-a-nutshell/ for a good interactive explanation, and https://online.stat.psu.edu/stat462/node/87/ for detail. See AEJ-leverage and NBER-leverage for examples of leverage in economics.
When two regressors carry nearly the same information, OLS cannot tell their separate effects apart.
The Variance Inflation Factor is useful as a quick diagnostic for overlapping information between regressors: a \(\hat{VIF}_{k}\) near \(1\) means \(\hat{x}_{k}\) is uncorrelated with the others, and a common rule of thumb flags \(\sqrt{\hat{VIF}_{k}} > 2\). Collinearity does not bias the coefficients, it only widens their standard errors so that coefficient estimates may change erratically in response to small changes in the model or the data; in the extreme case with more variables than observations (\(K>n\)), the linear model has infinitely many solutions.
# Variance Inflation Factor from its definition: VIF_k = 1/(1 - R^2_k),
# where R^2_k comes from regressing covariate k on the other covariates.
R2_assault  <- summary(lm(Assault ~ UrbanPop, data=xy_hat))$r.squared
R2_urbanpop <- summary(lm(UrbanPop ~ Assault, data=xy_hat))$r.squared

vif <- c(Assault=1/(1-R2_assault), UrbanPop=1/(1-R2_urbanpop))
vif
##  Assault UrbanPop
## 1.071828 1.071828

# A common rule of thumb flags sqrt(VIF) > 2
sqrt(vif) > 2
##  Assault UrbanPop
## FALSE FALSEThe second diagnostic plot (Q-Q normal of residuals) examines whether the residuals are normally distributed. Your OLS coefficient estimates do not depend on the normality of the residuals. (Good thing, because there’s no reason the residuals of economic phenomena should be so well behaved.) Many hypothesis tests are, however, affected by the distribution of the residuals. For these reasons, you may be interested in assessing normality.
par(mfrow=c(1, 2))
hist(resid(reg),
    main='Histogram of Residuals',
    font.main=1, border=NA)

qqnorm(resid(reg),
    main='Normal Q-Q Plot of Residuals',
    font.main=1, col=grey(0, .5), pch=16)
qqline(resid(reg), col=1, lty=2)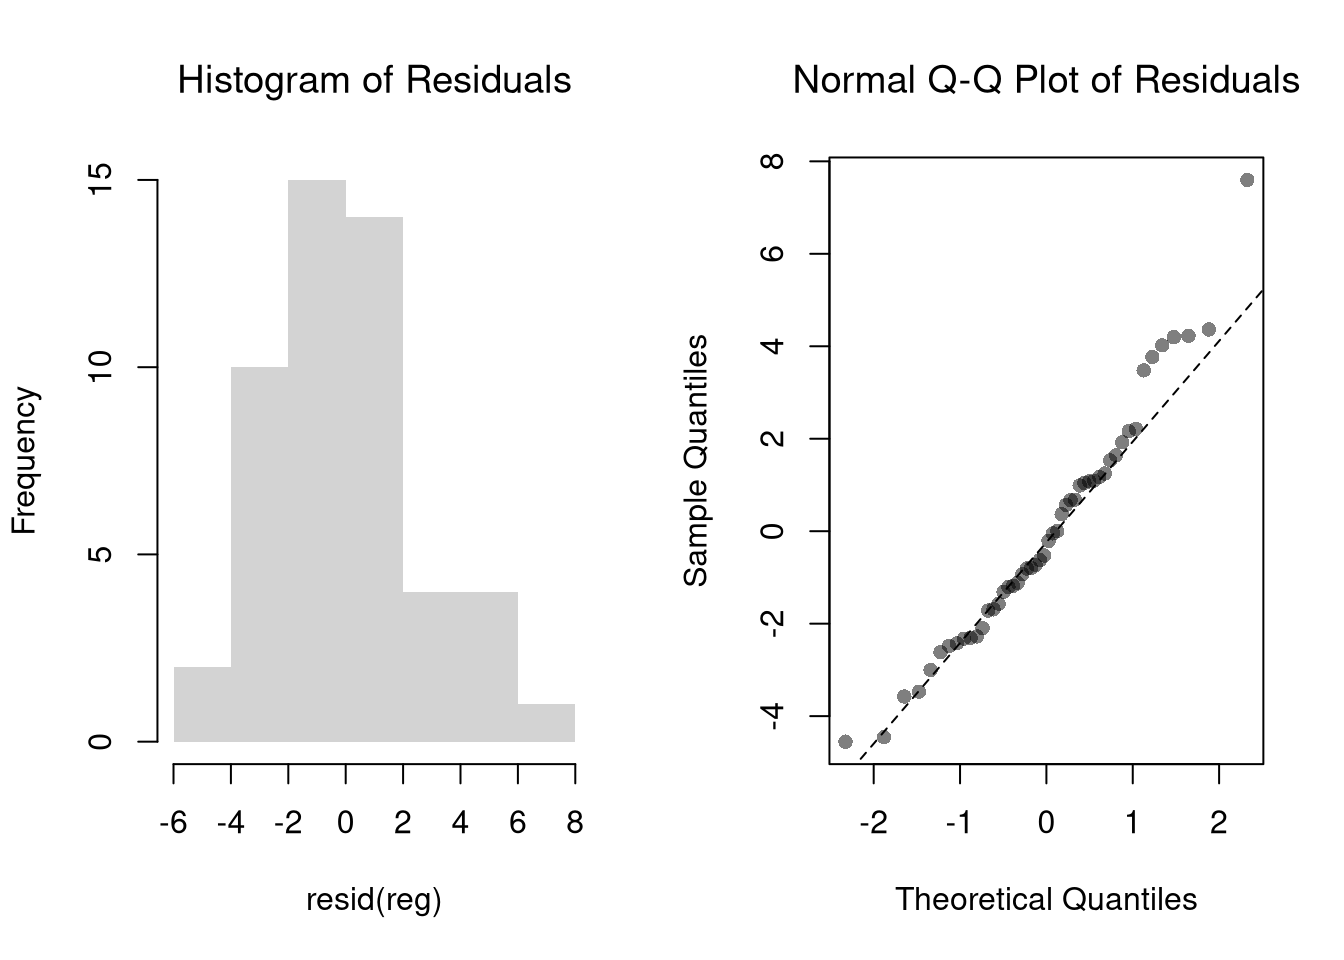
#shapiro.test(resid(reg))OLS treats the error variance as constant across observations, and when that assumption fails the coefficients are still fine but the standard errors are not.
Detecting heteroskedasticity is useful because the standard errors that R reports by default rely on a homoskedasticity assumption. If that assumption fails, every \(p\)-value and confidence interval based on those standard errors is wrong too, and typically too narrow. The third diagnostic plot (scale-location) is the visual check; the Breusch-Pagan test below is a numerical alternative.
# Breusch-Pagan test for heteroskedasticity, by hand.
# Regress the squared residuals on the original regressors:
# a good fit (high R^2) signals non-constant variance.
e_sq_hat <- resid(reg)^2
aux <- lm(e_sq_hat ~ Assault + UrbanPop, data=xy_hat)
R2_aux <- summary(aux)$r.squared

# Test statistic n*R^2 ~ chi-squared with K degrees of freedom
n <- nrow(xy_hat)
K <- 2
BP <- n*R2_aux
c(statistic=BP, p.value=1-pchisq(BP, df=K))
## statistic   p.value
## 1.9072736 0.3853371Transforming variables can often improve your model fit while still estimating it via OLS. This is because OLS only requires the model to be “linear in the parameters”. Under the assumptions of the model is correctly specified, the following table is how we can interpret the coefficients of the transformed data. (Note for small changes, \(\Delta ln(x) \approx \Delta x / x = \Delta x \% \cdot 100\).)
| Specification | Regressand | Regressor | Derivative | Interpretation (If True) |
|---|---|---|---|---|
| linear–linear | \(y\) | \(x\) | \(\Delta y = \beta_1\cdot\Delta x\) | Change \(x\) by one unit \(\rightarrow\) change \(y\) by \(\beta_1\) units. |
| log–linear | \(ln(y)\) | \(x\) | \(\Delta y \% \cdot 100 \approx \beta_1 \cdot \Delta x\) | Change \(x\) by one unit \(\rightarrow\) change \(y\) by \(100 \cdot \beta_1\) percent. |
| linear–log | \(y\) | \(ln(x)\) | \(\Delta y \approx \frac{\beta_1}{100}\cdot \Delta x \%\) | Change \(x\) by one percent \(\rightarrow\) change \(y\) by \(\frac{\beta_1}{100}\) units |
| log–log | \(ln(y)\) | \(ln(x)\) | \(\Delta y \% \approx \beta_1\cdot \Delta x \%\) | Change \(x\) by one percent \(\rightarrow\) change \(y\) by \(\beta_1\) percent |
Now recall from micro theory that an additively separable and linear production function is referred to as “perfect substitutes”. With a linear model and untransformed data, you have implicitly modelled the different regressors \(X\) as perfect substitutes. Further recall that the “perfect substitutes” model is a special case of the constant elasticity of substitution production function.
When linear-linear, log-log, and other named specifications are all plausible, we want one estimation procedure that searches across them rather than committing to one ex ante.
The Box-Cox family is useful when no single named specification is obviously right and we want the data to choose between linear, log, and intermediate fits by minimizing prediction error on the original scale (see http://dx.doi.org/10.2139/ssrn.3917397). The family also nests:
When \(\rho=\lambda\) we get the CES production function, which spans the “perfect substitutes” linear-linear model and the “cobb-douglas” log-log model among others. In this CES case, \(\rho~\text{in}~(-\infty,1]\) controls the substitutability of explanatory variables (\(\rho<0\) is “complementary”) and \(\lambda\) governs the returns to scale (\(\lambda<1\) is “decreasing returns”).
We compute the mean squared error in the original scale by inverting the predictions; \[ \hat{y}_{i}^{\mathrm{fit}} = \begin{cases} \left[ \hat{y}_{i}^{\mathrm{fit},(\lambda)} \cdot \lambda \right]^{1/\lambda} -1 & \lambda \neq 0 \\ \exp\left( \hat{y}_{i}^{\mathrm{fit},(\lambda)} \right) -1 & \lambda=0 \end{cases}. \]
It is easiest to optimize parameters in a 2-step procedure called concentrated optimization. We first solve for \(\hat{\mathbf{b}}(\rho,\lambda)\) and compute the mean squared error \(MSE(\rho,\lambda)\). We then find the \((\rho,\lambda)\) which minimizes \(MSE\).
# Box-Cox Transformation Function
bxcx <- function( xy, rho){
    if (rho == 0L) {
      log(xy+1)
    } else if(rho == 1L){
      xy
    } else {
      ((xy+1)^rho - 1)/rho
    }
}
bxcx_inv <- function( xy, rho){
    if (rho == 0L) {
      exp(xy) - 1
    } else if(rho == 1L){
      xy
    } else {
     (xy * rho + 1)^(1/rho) - 1
    }
}

# Which Variables
reg <- lm(Murder ~ Assault+UrbanPop, data=xy_hat)
X <- xy_hat[, c('Assault', 'UrbanPop')]
y_hat <- xy_hat[, 'Murder']

# Simple Grid Search over potential (Rho, Lambda)
rl_df <- expand.grid(rho=seq(-2, 2, by=.5), lambda=seq(-2, 2, by=.5))

# Compute Mean Squared Error
# from OLS on Transformed Data
errors <- apply(rl_df, 1, function(rl){
    Xr <- bxcx(X, rl[[1]])
    y_trans_hat <- bxcx(y_hat, rl[[2]])
    xy_trans_hat <- cbind(Murder=y_trans_hat, Xr)
    Regr <- lm(Murder ~ Assault+UrbanPop, data=xy_trans_hat)
    y_fit <- bxcx_inv(predict(Regr), rl[[2]])
    e_hat  <- (y_hat - y_fit)
    return(e_hat)
})
rl_df$mse <- colMeans(errors^2)

# Want Small MSE and Interpretable
layout(matrix(1:2, ncol=2), width=c(3, 1), height=c(1, 1))
par(mar=c(4, 4, 2, 0))
plot(lambda ~ rho, rl_df, cex=8, pch=15,
    xlab=expression(rho),
    ylab=expression(lambda),
    col=hcl.colors(25)[cut(1/rl_df$mse, 25)])
# Which min
rl0 <- rl_df[which.min(rl_df$mse), c('rho', 'lambda')]
points(rl0$rho, rl0$lambda, pch=0, col=rgb(0, 0, 0, .8), cex=8, lwd=2)
# Legend
plot(c(0, 2), c(0, 1), type='n', axes=FALSE,
    xlab='', ylab='', cex.main=.8,
    main=expression(frac(1, 'Mean Square Error')))
rasterImage(as.raster(matrix(hcl.colors(25), ncol=1)), 0, 0, 1, 1)
text(x=1.5, y=seq(1, 0, l=10), cex=.5,
    labels=levels(cut(1/rl_df$mse, 10)))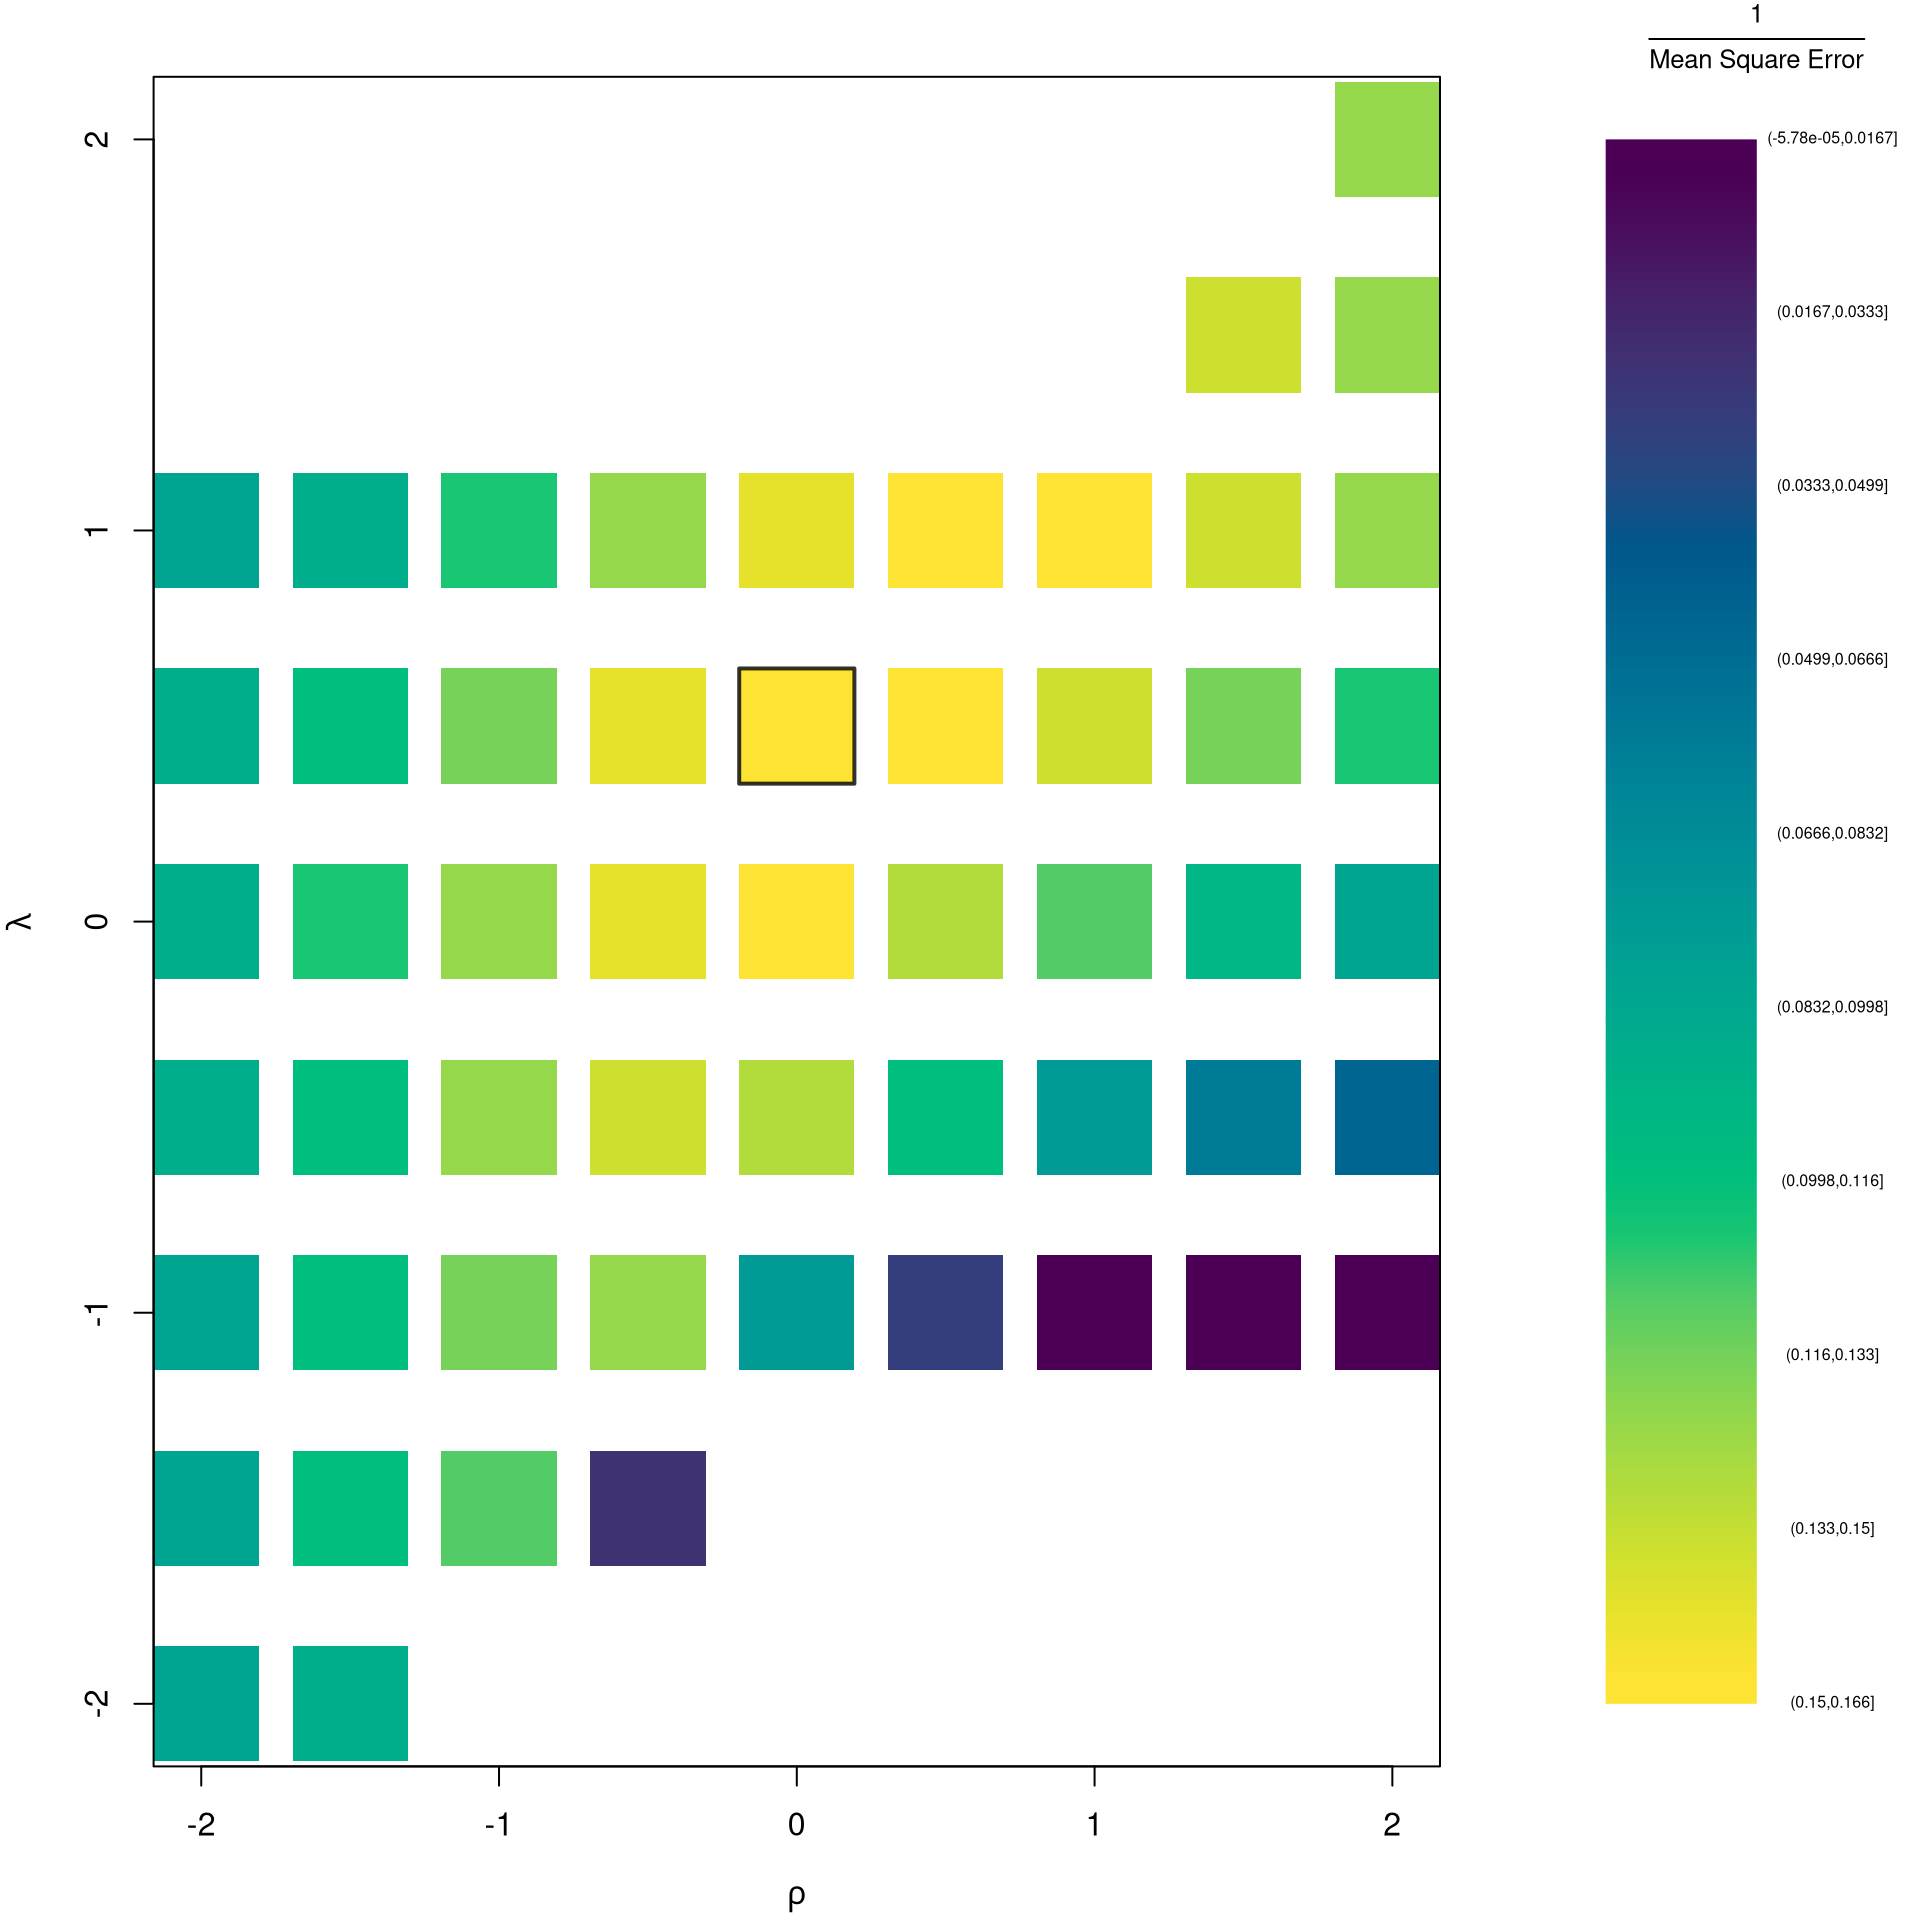
The parameters \(-1,0,1,2\) are easy to interpret and might be selected instead if there is only a small loss in fit. (In the above example, we might choose \(\lambda=0\) instead of the \(\lambda\) which minimized the mean square error). You can also plot the specific predictions to better understand the effect of data transformation beyond mean squared error.
# Plot for Specific Comparisons
Xr <- bxcx(X, rl0[[1]])
y_trans_hat <- bxcx(y_hat, rl0[[2]])
xy_trans_hat <- cbind(Murder=y_trans_hat, Xr)
Regr <- lm(Murder ~ Assault+UrbanPop, data=xy_trans_hat)
y_fit <- bxcx_inv(predict(Regr), rl0[[2]])

cols <- c(rgb(1, 0, 0, .5), col=rgb(0, 0, 1, .5))
plot(y_hat, y_fit, pch=16, col=cols[1], ylab='Prediction', xlab='Observed Murder',
    main=NA, ylim=range(y_hat, y_fit))
points(y_hat, predict(reg), pch=16, col=cols[2])
legend('topleft', pch=c(16), col=cols,
    title=expression(rho~', '~lambda),
    legend=c( paste0(rl0, collapse=', '), '1, 1') )
abline(a=0, b=1, lty=2)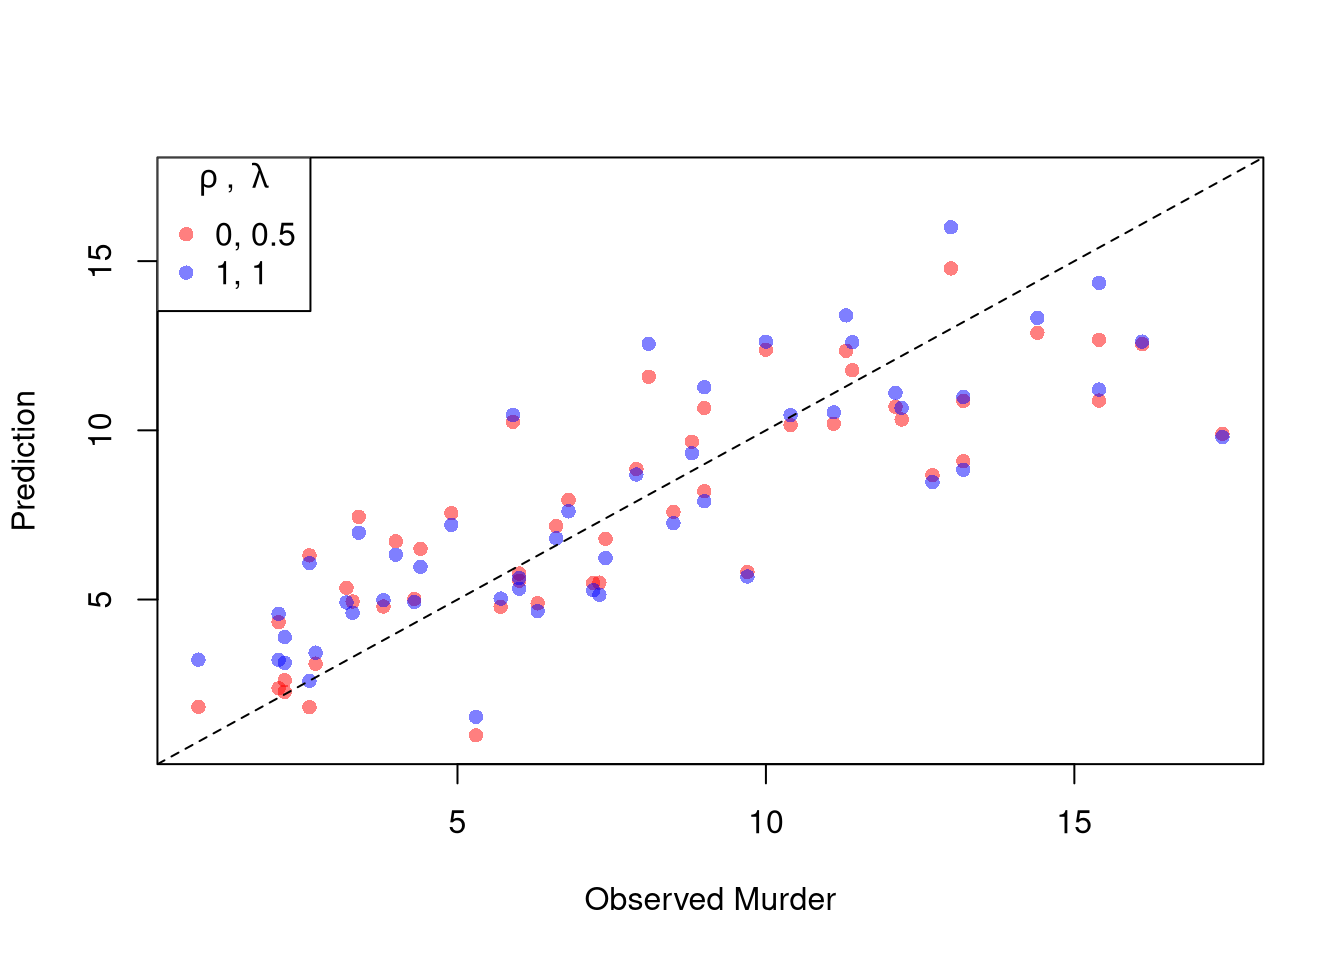
We can compare the fit on the original scale: the grid-search optimum versus the untransformed linear baseline.
# Compare prediction MSE on the original Murder scale
mse_linear <- mean(resid(reg)^2)
mse_boxcox <- min(rl_df$mse)
c(rl0, mse_linear=round(mse_linear, 3), mse_boxcox=round(mse_boxcox, 3))
## $rho
## [1] 0
##
## $lambda
## [1] 0.5
##
## $mse_linear
## [1] 6.257
##
## $mse_boxcox
## [1] NaN
The Box-Cox grid lowers the prediction MSE relative to the linear baseline, at the cost of two extra parameters and a less direct interpretation of the coefficients.
When explicitly transforming data according to \(\lambda\) and \(\rho\), these parameters increase the degrees of freedom by two. The default hypothesis testing procedures do not account for you trying out different transformations, and should be adjusted by the increased degrees of freedom. Specification searches deflate standard errors and are a major source for false discoveries.
Note that if you are ultimately interested in the outcome \(Y\), then transforming/untransforming \(Y\) can introduce a bias. To understand when you might be better off sticking with an untransformed outcome variable, see the literature on “smearing”.
Comment the script you wrote for this chapter, then restart R and check that it runs from a clean session, then check the script with AI as explained in Working with AI. Write three sentences from memory on the main statistical idea of this chapter, and ask the assistant what is wrong, vague, or missing. Finish with your own questions about whatever you found hardest.
A regression has high \(\hat{R}^2\) but one observation has a very large Cook’s Distance. Should you automatically drop that observation? Explain what Cook’s Distance measures and describe a situation where keeping the outlier is the right choice.
Using the USArrests dataset, fit lm(Murder ~ Assault + UrbanPop). Produce the four standard diagnostic plots with plot(). Identify the state with the highest leverage (using hatvalues()) and the state with the largest standardized residual (using rstandard()). Are they the same state?
Fit the model lm(Murder ~ Assault + UrbanPop, data=xy_hat) and then fit a log-linear version lm(log(Murder + 1) ~ Assault + UrbanPop, data=xy_hat). Compare the two models by computing the mean squared prediction error in the original (untransformed) scale for each. Which specification fits better?
This chapter audited a fitted regression with four diagnostic plots (outliers, leverage, normality, scale) and three numerical companions: the Variance Inflation Factor for collinearity, the Breusch-Pagan test for heteroskedasticity, and Box-Cox transformations as a way to rescue a misspecified linear model. The Box-Cox grid-search on Murder ~ Assault + UrbanPop made the trade-off concrete: searching over \((\rho, \lambda)\) on \(\{-2, -1.5, \ldots, 2\}^2\) found a fit with lower MSE on the original Murder scale than the untransformed baseline.